In detail
1. The source count is the thing that broke centralization
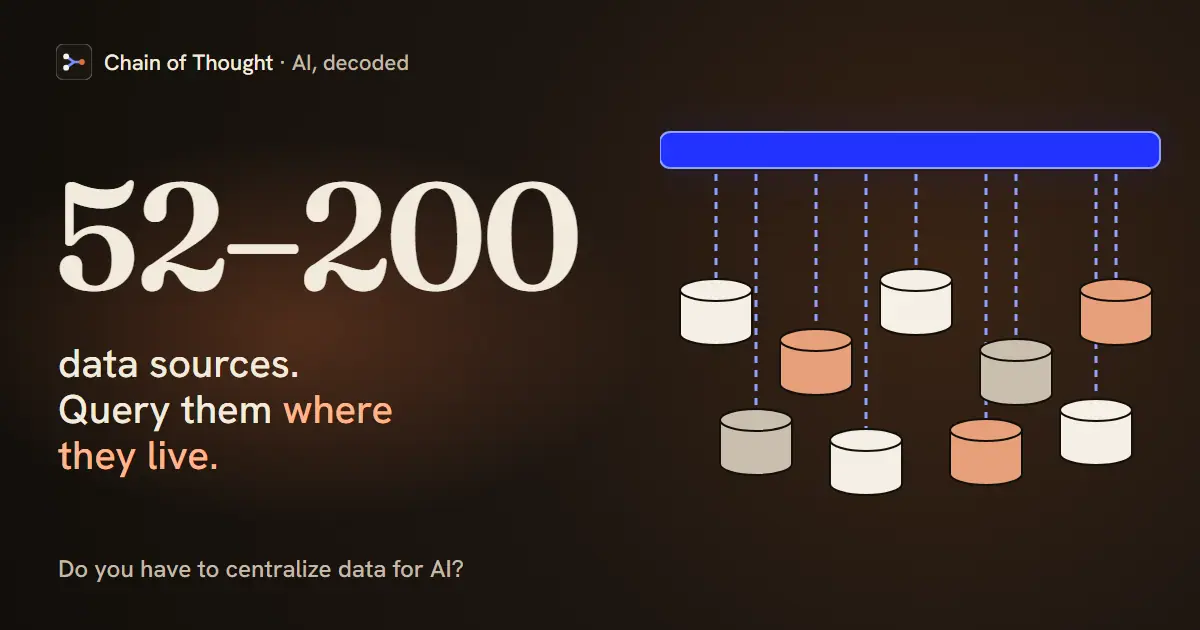
Jitender Aswani, SVP of Engineering and Security at Starburst, puts the number plainly: “A traditional enterprise will have anywhere between 52 to 200 data sources” (15:11). His account of how they got there is ordinary rather than dramatic. Every SaaS tool and cloud service a company buys generates and stores its own data, so the source count grows with every tool a company adds.
Centralization was, in his words, “a fine, fine strategy. when the data was growing not as fast as your ability to move it.” That condition stopped holding. His framing is that federation “is the only model that scales with entropy,” a claim he states flatly in the episode’s cold open and hedges to “I think” when he makes it in full (28:54).
2. Moving the data does not end the work, it changes it
The pitch for a lake was that once everything lands in one place the problem is solved. Aswani’s read is the opposite: “Your problem starts to compound when you have moved all your data. Now you have a governance problems. you have this continuous ETL challenges” (28:54).
The mechanism is that data is not static. A SaaS vendor adds a column, and the pipeline that imported that table has to be retooled; until it is, someone is debugging why it fails. He describes leaders “spending days debugging why my pipelines are failing” (28:54) as the steady state, not the incident.
3. Agents made the bill arrive sooner
Agents query differently from people. Aswani describes them operating in a reason-and-act loop, “generating queries at insane speed” (32:50), including unbounded ones, because an agent that lacks an answer fires another query rather than stopping to ask whether it should. When Starburst shipped its own MCP server, “we saw the query volume go through roof,” (32:50) and customers had to scale compute behind it.
The failure he offers is his own team’s. Their internal FinOps agent had access to AWS cost data but not GCS or Azure. Asked to break spend down by cloud provider, “it starts fighting queries. It’s just frantically fighting queries without stepping back and thinking, do you even have GCS and Azure data?” (38:21). That agent did not report its partial access. It worked harder.
4. Federation is a compute layer, not another copy
The alternative Aswani describes is to accept the fragmentation and move the compute instead: “the best way to live with that challenge is to actually put a virtual compute layer on top through data federation.” The data stays where it is; the query engine reaches across (15:11). In Trino, the open-source engine Starburst builds on, that reach comes from connectors: each one adapts the engine to a data source such as a data lake or a relational database.
He extends the same argument to context. Knowing where the data lives is not sufficient, because meaning is scattered too: whether “customer” means account or opportunity, whether the fiscal year starts in February or July. His term for the layer that holds this is a context graph, which he distinguishes from a knowledge graph: the knowledge graph carries entities and relationships, and the context graph adds the business rules on top of them.
Not every guest treats centralization as the problem. In episode 26 at 36:42, Databricks’ Carly Taylor, speaking about game studios, describes AI working natively inside the data platform once data is centralized, governed and built into a business-ready layer. The condition she stresses is metadata, “a description of what all your data actually is,” which she says is harder to come by in gaming than you would think (37:42). With it, she says, people who don’t write SQL can ask questions of their data in plain language. Taylor works for a vendor of the centralized platform and Aswani for a vendor of federation, so read both as positions. Both arguments still depend on a description of what the data means. The episode was sponsored by Galileo.
Make incomplete coverage visible
Federation changes where the query runs; it does not mean no data moves. In Trino, the coordinator and workers access the connected sources and spread each query across the cluster (Trino, Concepts). Trino’s pushdown documentation says support for delegating work to a source “is specific to each connector” and the underlying system, so inspect the query plan and measure representative workloads rather than assuming every filter or join runs at the source.
Coverage gaps are the other risk. At 38:21, Aswani describes Starburst’s internal FinOps agent: it was built on AWS spend data, while Azure and GCS data still needed a pipeline before it was queryable, so the agent “doesn’t give us full picture.” That is one reported internal example, not a measured failure rate for agents or federation.
Fictional check: a test ledger holds $120 of AWS spend and $30 of Azure spend, and the agent can reach only the AWS source. A correct answer reports the $120 subtotal and names the missing Azure coverage; it does not call $120 the total or treat unavailable data as zero. Set query, time and spending limits outside the model so retries against a missing source cannot run indefinitely.
Why it matters
If a data-consolidation program is still underway when the agent pilot starts, the pilot does not wait for it. If the honest answer to “which systems can this agent reach” is a subset, decide that deliberately and tell the agent. Aswani’s FinOps agent did not work it out on its own. It just kept querying.
Federation solves reach, not authority. The separate question is how identity, source-level policy, and action controls combine once an agent can query across systems. See agent identity and permissions for that ownership model.
Disclosure: Episodes 26 and 27 aired in season two, which Galileo sponsored while Conor worked there; both episodes’ show notes carry a Galileo block.
Hear it from the guest
“So, up until a point, centralization works fine. But as the data volume continues to explode, the ETL tech debt starts to really accumulate.”
“And sometimes I've seen that like after 30 minutes, they're still doing it. And I know you are wasting my tokens. Just stop. I sent you on a wild goose chase and you did go on that wild goose chase.”
“If you point to any given file anywhere in their environment, chances are there's three, four or five copies of that piece of data”
“Once you have good metadata, you can ask AI to almost anything about your data.”
Quotes lightly edited to remove filler words.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
Concepts in this explainer
Data PipelineData LakeConversational AnalyticsData WarehouseQuery DecompositionSystem of RecordContext GraphKnowledge Graph