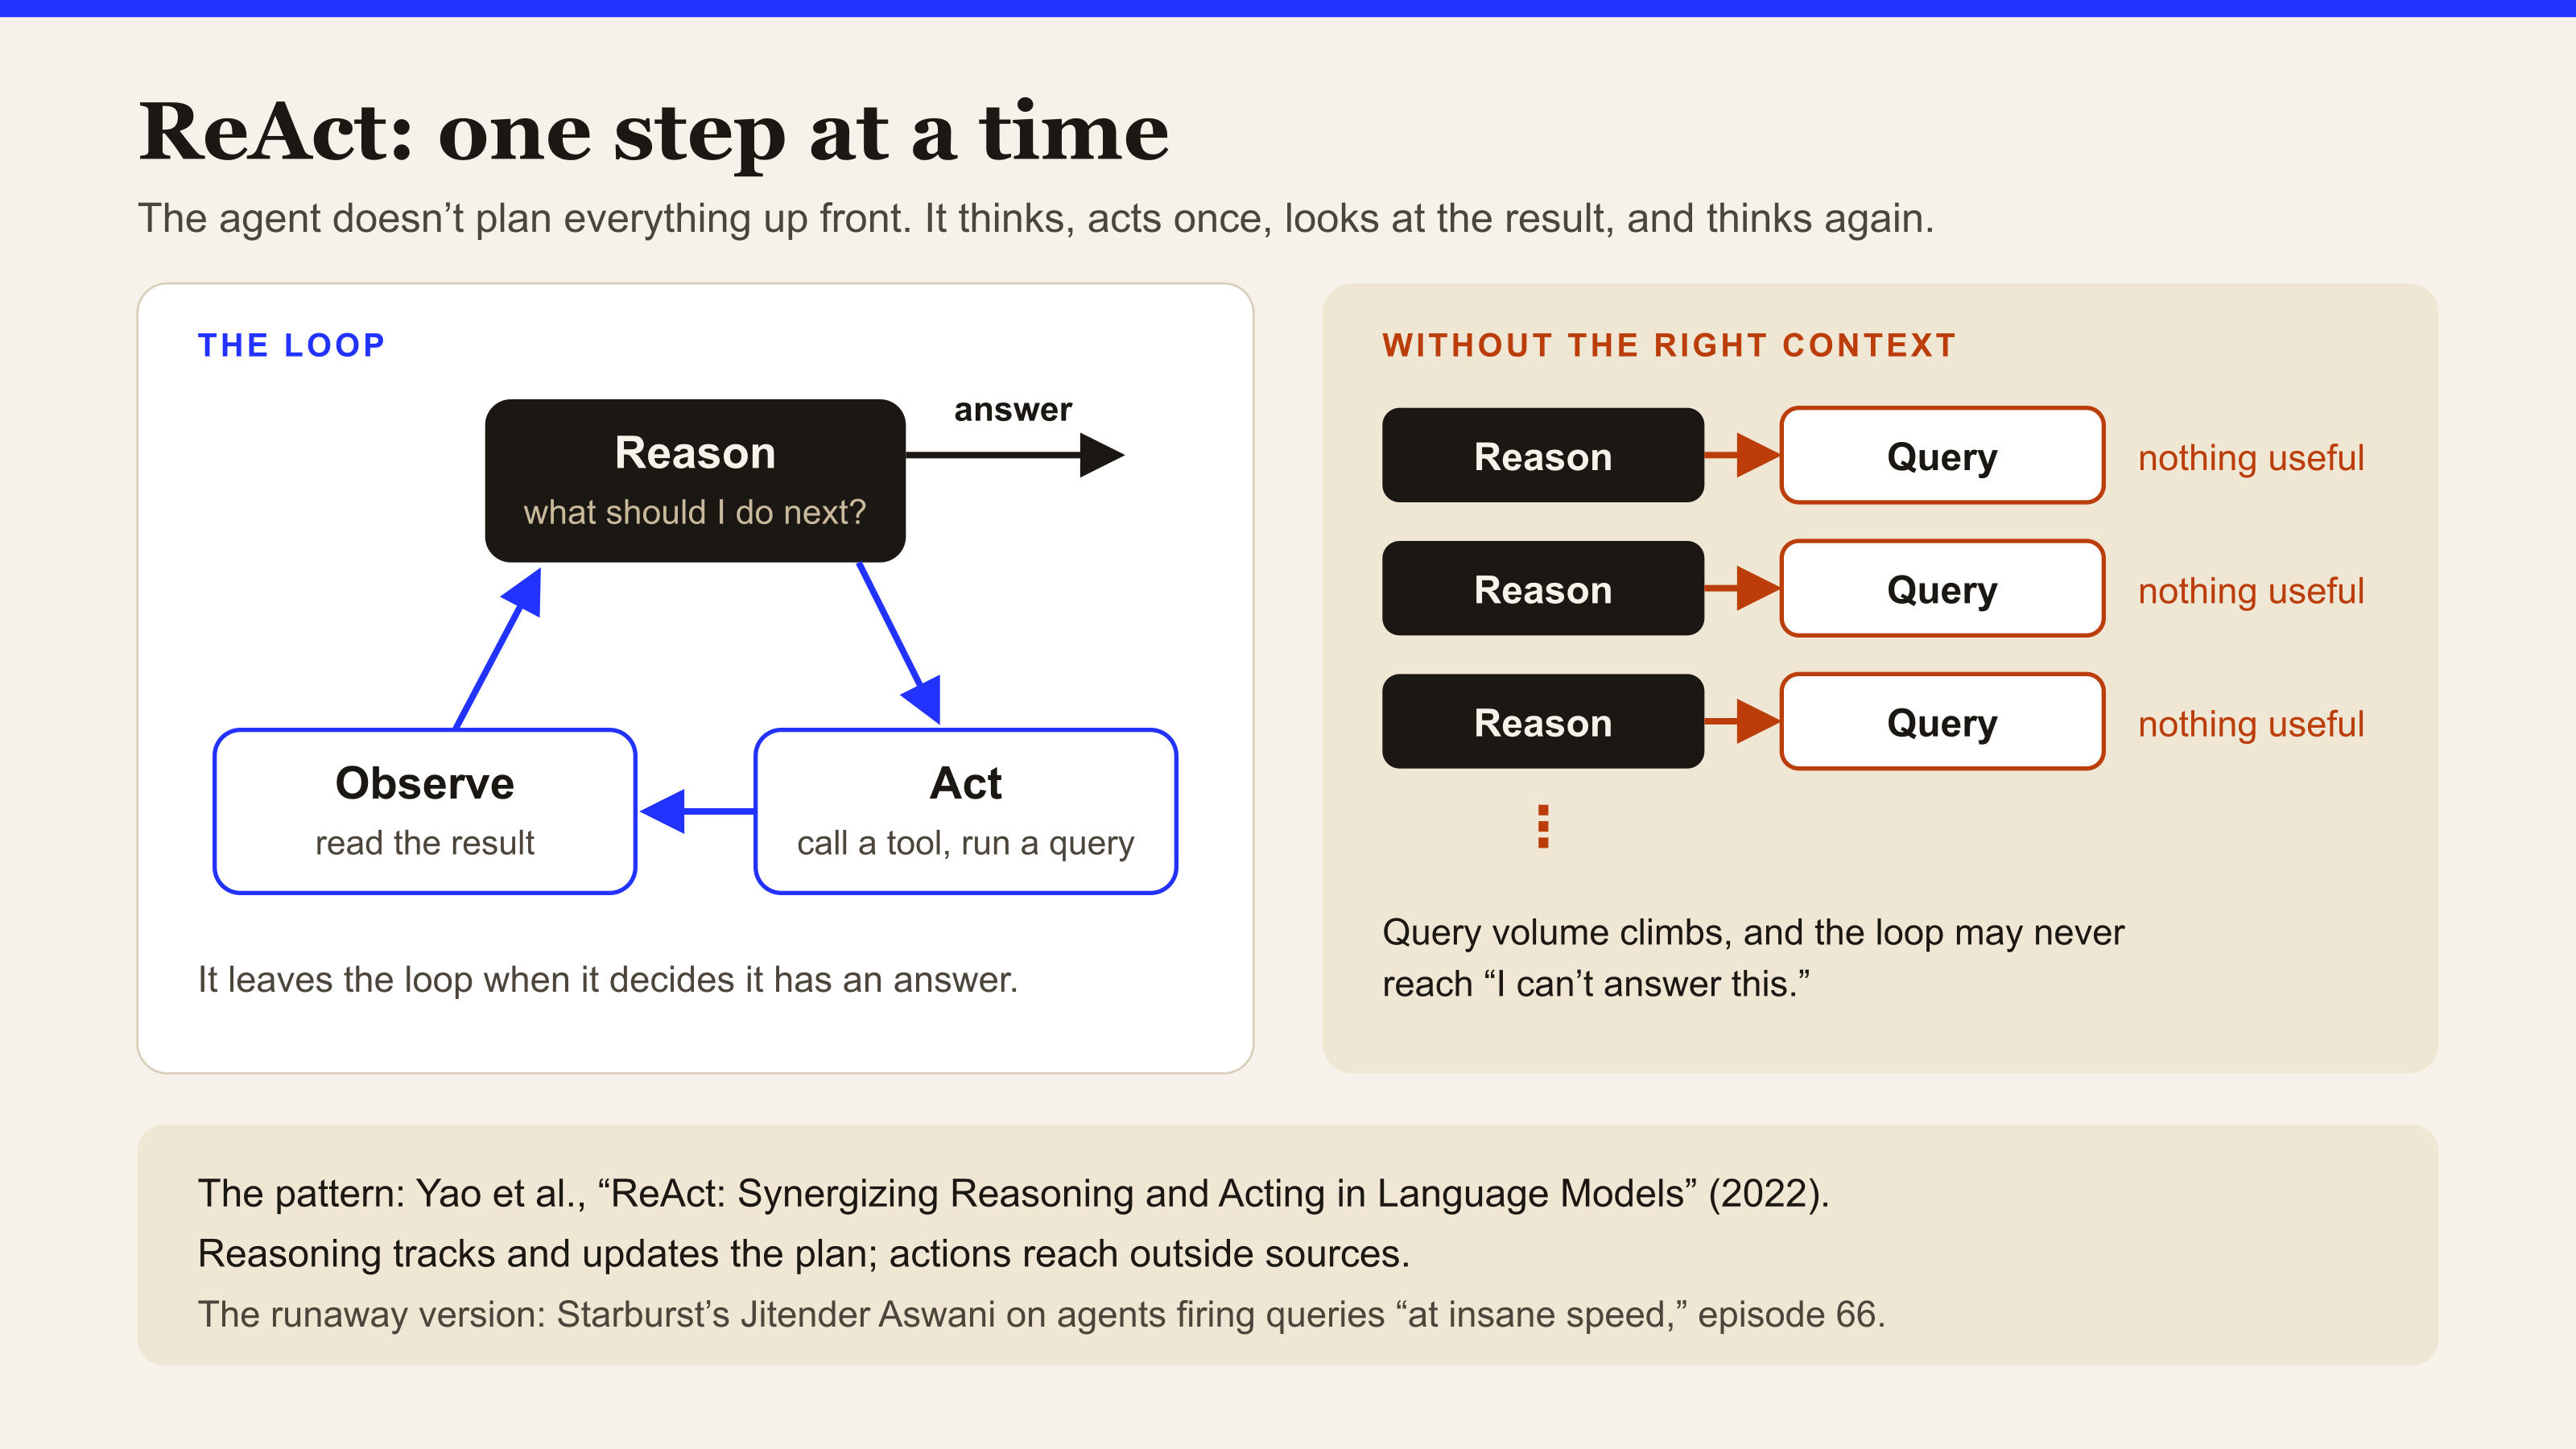
The name comes from the 2022 paper ReAct: Synergizing Reasoning and Acting in Language Models by Yao and colleagues, which prompts a model to generate reasoning traces and task actions in an interleaved way: the reasoning tracks and updates the plan, and the actions let it work with external sources, such as a knowledge base or an environment.
In a ReAct loop, an agent doesn’t have to fix its full approach up front: it reasons about what to do next, takes an action, observes the result, and revises the plan. The paper also allows several actions between reasoning steps for decision-making tasks, so a thought before every single tool call is not the definition. This makes agents adaptive, but it also means an agent with incomplete context can get stuck repeatedly firing queries against data it doesn’t actually have access to, unable to reason its way to ‘I can’t answer this.’
Starburst’s Jitender Aswani ties this loop to the surge in query volume his data platform saw as agents came online, including unbounded queries fired by agents that lacked the context to recognize a dead end, and a jump when Starburst launched its own MCP server (episode 66, 32:50). That is his account of one platform’s traffic, not a controlled comparison of agent designs.
Follow a request through the loop
An invented, read-only example: an agent is asked whether a fictional SDK’s v2 release supports batch publishing.
| Step | What happens |
|---|---|
| Reason, then act | The answer needs v2 evidence, so the agent requests the v2 release notes instead of guessing from an older version. |
| Observe | The tool returns only the v1 notes. That is the wrong version, not confirmation either way. |
| Revise or stop | The agent tries another version-specific source within its call budget. If the evidence is still missing, it answers “unresolved” and names the gap. |
The last row is the step the episode 66 agents skipped. A prompt alone does not enforce it: set a call budget and a missing-evidence exit in the application, then record requested and executed calls, repeated requests and the final answer for each test case. The ReAct paper’s own error analysis lists repeated thoughts and actions that fail to escape a loop as one failure pattern (Yao et al., section 3.3). A short trace can still be wrong, and a long one can be necessary, so judge both the answer and the calls it took.
Hear it from the guest
“They operate in this react mode, they reason, they act, they reason, they act, they are generating queries at insane speed.”
Quotes lightly edited to remove filler words.
Sources
- Yao et al.: ReAct: Synergizing Reasoning and Acting in Language Models — The paper that interleaves reasoning traces with actions and observations from external sources.
Go deeper
- How does an AI agent decide which tool to use? AI, decoded · How AI Agents Use Tools
- What's the difference between agentic and non-agentic AI? AI, decoded · Agentic vs. Non-Agentic AI
- Do you have to centralize your data before AI agents can use it? AI, decoded · Centralizing Data Before AI: Why the Lake Doesn't Save You