In detail
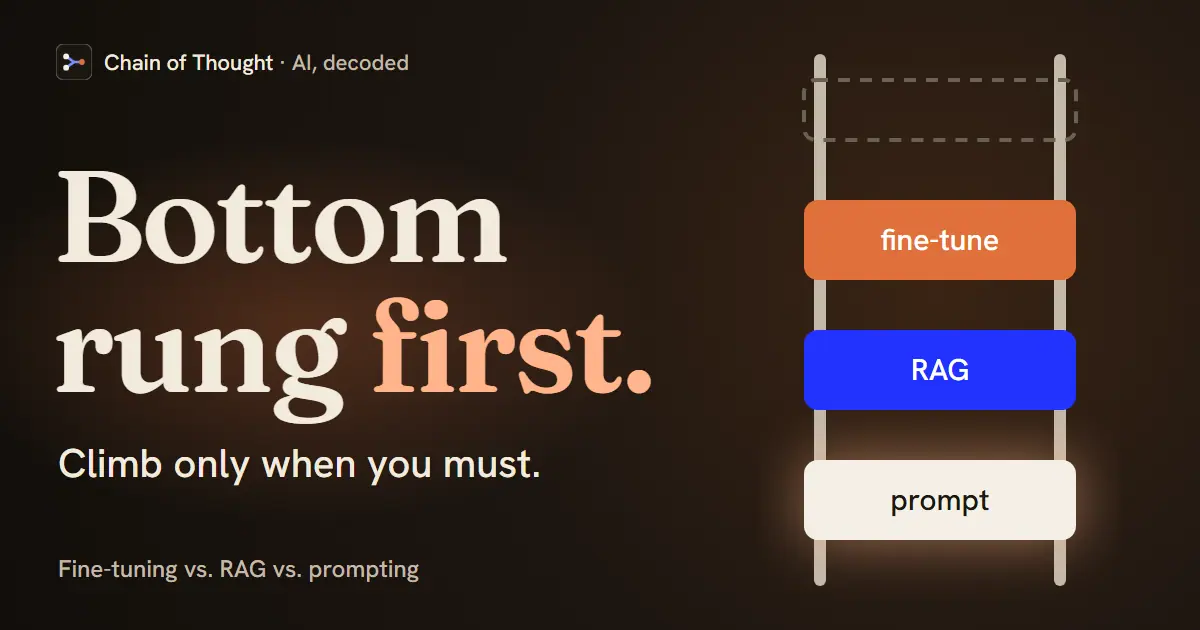
These three get pitched as rivals, but they solve different problems and stack cleanly. The useful framing — echoed by Databricks’ Denny Lee on the show — is a ladder: try the cheap thing first, measure, and only climb a rung when the result demands it.
1. Prompting — start here, always
Prompt engineering shapes the model’s behavior through the instruction alone: the wording, the examples, the output format. No infrastructure, instant to iterate, and on modern models it gets you further than people expect. If a better prompt solves it, you’re done — don’t build anything.
2. RAG — when the answer depends on your data
Retrieval-augmented generation fetches relevant documents at answer time and gives them to the model, so responses are grounded in your sources rather than the model’s frozen training data. Denny Lee’s example on the show is asking your company’s model for the CEO’s salary: rather than constantly retraining it to stay current, point it at a database or vector store that holds the exact figure. That keeps answers current, lets you cite where they came from, and is a main lever against hallucination — all without touching the model. If the problem is what the model knows, RAG is usually the answer.
3. Fine-tuning — when behavior must change
Fine-tuning adjusts the model’s weights on your examples. It’s the right tool when you need a consistent style or format, a specialized skill, or lower latency on a narrow task — things prompting can’t reliably pin down. It’s also the most expensive and brittle option: you need quality training data and a pipeline to retrain as things change. Denny Lee’s ladder puts it after RAG, agents, and a first pass with example questions and answers, with pretraining your own model further up, for a reason — reach for it for how the model behaves, rarely for what it knows.
The decision in one line
Prompting changes the instruction; RAG changes the context; fine-tuning changes the model. Knowledge that updates → RAG. Behavior that must be consistent → fine-tuning. Everything else → prompting first.
Why it matters
The common failure is starting at the top of the ladder — fine-tuning a model to teach it facts that change weekly, when RAG would have been cheaper and stayed current. Match the technique to the problem, climb only when you’ve measured a real gap, and remember the rungs combine: a fine-tuned model fed by RAG and steered by a good prompt is a normal production setup.
Hear it from the guest
“You could take a smaller model. You can agentify it. You can ragify it. You can then go up the ladder to fine tune it before you ever need to do all these other things.”
“So instead of actually going ahead and trying to have the LM figure it out, I'm going like maybe, just maybe you can refer to some other database or a vector store or hell at this point, a lake house, somewhere that solidly says what the actual value is.”
“You've got like 50 special cases in your prompt and you're overloading your prompt And you just realize, no, I could like post-train these 50 special cases in”
Quotes lightly edited to remove filler words.
Go deeper
- Fine-tuning a model with the Trainer API Inspect what training changes in a BERT sentence-pair classifier and how validation metrics are measured. Assumes the preceding setup and data-preparation lesson; a GPU is more practical for training.
- Retrieval augmented generation Compare the training example with a workflow that retrieves document chunks for generation. Requires a running instance and a configured generative model; provider usage may cost money.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
Concepts in this explainer
Post-trainingSupervised Fine-TuningRetrieval-Augmented Generation (RAG)Fine-TuningAI HallucinationPrompt EngineeringLatencyPre-training