In detail
The data boundary problem
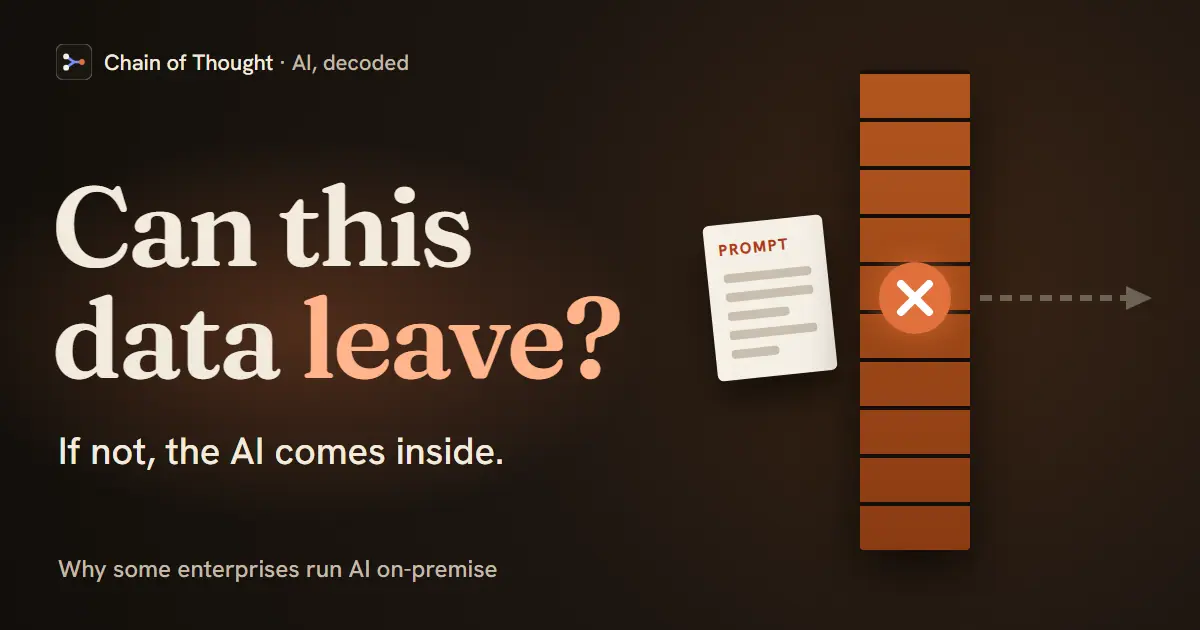
A hosted AI service works by receiving your input. For most companies that’s fine. For a hospital, a bank, or a defense contractor, it’s a non-starter: the prompt itself contains data that legally or contractually cannot leave their environment. No amount of provider security solves it, because the problem is the boundary crossing, not the provider.
What goes on-premise
It’s not just the model. To run AI behind the firewall you need the whole pipeline inside the perimeter — the model, the data it draws on, and the observability and evaluation stack that lets you trace and trust it. Observability is the part teams forget: if you can’t send traces to an outside tool, you have to monitor agents with something that also runs on-prem, or you’re flying blind in the one environment where mistakes are most costly.
The trade-offs
On-premise buys control and compliance at the price of convenience. You own the infrastructure, the scaling, the model updates, and the operational burden that a hosted provider would otherwise carry. That’s why it’s the right answer for regulated, high-sensitivity workloads and the wrong answer for a team that could simply use a hosted API. On-premise is also no longer limited to open models: Google, for one, offers Gemini on its air-gapped data-center platform. The deciding question isn’t “is on-prem better” — it’s “can this data leave.”
Hear it from the guest
“So in our platform today, you can take the whole platform and deploy it on basically the platform of your choice, either on premises or the cloud of your choice, right?”
“Can you bring the model to the data instead of sending off the data to the model somewhere else?”
Quotes lightly edited to remove filler words.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
Concepts in this explainer
On-Premises AIModel ServingSovereign AIAudit TrailData CenterFrontier Model