In detail
Find the cost before you cut it
Agent bills are rarely one big line item; they’re a thousand small calls. Without tracing, teams guess at where the money goes and optimize the wrong thing. Start by instrumenting the agent so you can see cost per step, per task, and per model call. The expensive patterns — a loop that retries silently, a step that calls the model three times when once would do — only show up when you can see the trace.
Right-size the model
The most common waste is sending every step to the biggest, most expensive model. Many steps don’t need it. Routing easy or structured sub-tasks to a smaller or cheaper model, and reserving the frontier model for the hard reasoning, can cut cost sharply with little quality loss. Intercom’s move from a general frontier model to a tuned smaller one is the extreme version of this: pick the cheapest model that still passes your evals.
Trim and cache context
Agents can accumulate irrelevant context over successive steps. Inspect what each step actually needs, trim carefully, and test whether summarization drops necessary evidence. Provider prefix caching can reuse processing of matching context; it does not remove that context from the request or make every cached token free.
Kill the failure tax
Failures are expensive twice: the wasted call that failed, and the retry. An agent that loops, picks the wrong tool, or recovers badly burns budget on work that produces nothing. Fixing the top failure modes is a cost optimization as much as a reliability one — and latency work, like Superhuman’s, often cuts cost in the same pass.
Try it: a minimal cost tracer
The useful unit is the completed task, not the single call. A cheaper call is a bad trade if total cost per successful task goes up, or if quality or latency falls below what the product needs. In practice:
- Record a cost event for every attempt. Give each task an ID, and log each model call with its step name, model, input and output tokens, attempt number, outcome, and estimated cost. Keep failed attempts in the totals: a retry that eventually succeeds still cost money.
- Rank steps by cost per completed task. Group the events by step and model, then read a few full traces of the most expensive step before you touch prompts or providers. Look for repeated calls with the same input, context that stopped helping, and tool results nobody uses.
- Make a cheaper model pass a step-specific eval. Build the eval from real examples of that step, including past failures, and set the quality bar before you look at the savings.
- Confirm it in production. Pick an outcome metric that a cheaper model can’t improve by doing less.
Illustrative sketch, not production code. call_model stands in for your provider client and is assumed to return token usage even when an attempt fails. The price table holds your current rates.
PRICE_PER_MILLION = {}  # model_id: (input_usd, output_usd)
events = []

def traced_step(task_id, step, model, prompt, max_attempts=2):
    input_rate, output_rate = PRICE_PER_MILLION[model]

    for attempt in range(1, max_attempts + 1):
        reply = call_model(model, prompt)  # ok, text, token counts
        cost = (
            reply["input_tokens"] * input_rate
            + reply["output_tokens"] * output_rate
        ) / 1_000_000

        events.append({
            "task_id": task_id,
            "step": step,
            "model": model,
            "attempt": attempt,
            "input_tokens": reply["input_tokens"],
            "output_tokens": reply["output_tokens"],
            "cost_usd": cost,
            "ok": reply["ok"],
        })

        if reply["ok"]:
            return reply["text"]

    raise RuntimeError(f"{step} failed after {max_attempts} attempts")
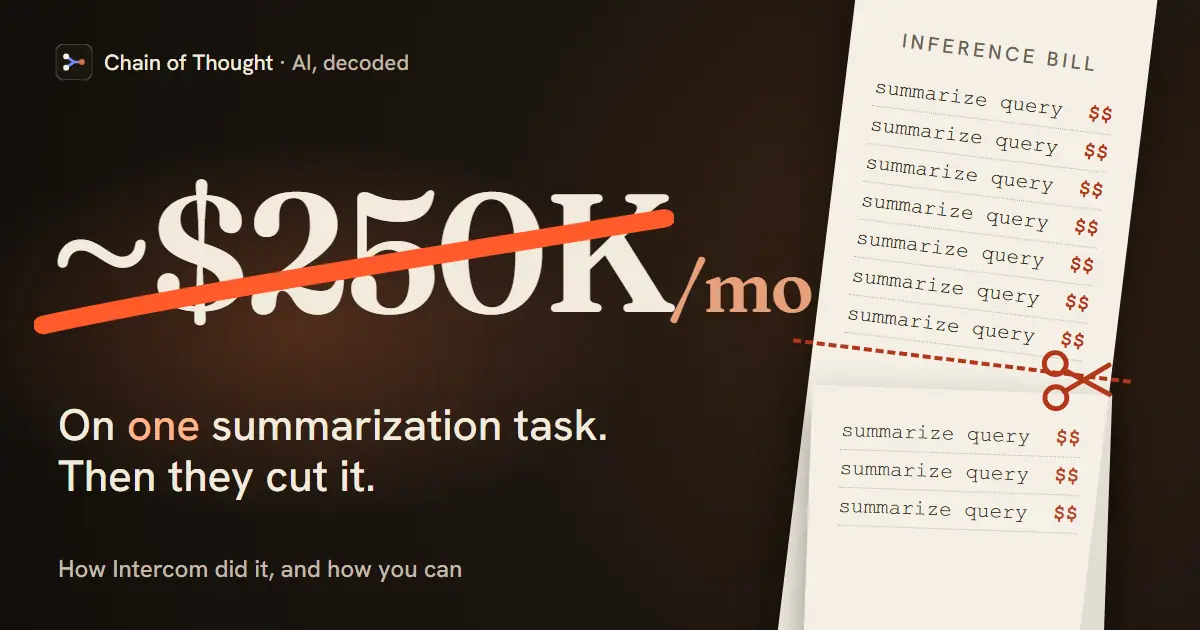
Intercom’s case shows what steps 2 to 4 look like at scale. The expensive step was query canonicalization, which rewrites each user question before retrieval, and it ran on GPT-4.1. Intercom post-trained a 14-billion-parameter Qwen model for that one job and kept Claude Sonnet on Fin’s hardest prompt: answering the end user’s question. Fergal Reid, Intercom’s Chief AI Officer, said every model is A/B tested before it reaches production, against two numbers. Soft resolutions, where Fin gives an answer it believes is correct, offers a human, and the user leaves without replying, should go up. Hard resolutions, where the user confirms the answer resolved their question, must not go down. The goal, in his words, is to avoid “building a deflection machine.”
Update, October 2026: Reid wrote on LinkedIn that Intercom has since switched to Nvidia and Google base models: “The important piece is a post training pipeline that works well, not any one base model.”
Superhuman’s auto-labels followed the same order. CTO Loïc Houssier described running email classification (is this an FYI, a pitch, a newsletter?) on a frontier model for every email a user has. Once the team knew which 10 or 12 labels users found useful, he said, the job moved to fine-tuned BERT-style classifiers on cheap, dedicated inference infrastructure.
Compare cost per verified success
Illustrative arithmetic, not provider pricing: route A costs $0.10 per attempt and succeeds on 90 of 100 tasks. Route B costs $0.06 and succeeds on 50. Before retries and human review, A costs $10 / 90 = about $0.11 per successful task; B costs $6 / 50 = $0.12. The cheaper attempt did not buy the cheaper successful outcome.
Use the same task mix and success definition for the comparison. Count failed runs, tool charges, retries and human handling. Then inspect the quality and latency distribution: an average can hide a costly tail of failures or a slow experience for the users who need help most. Do not compare a completed agent workflow with a cheap model call that leaves the work to a person.
Account for cache writes and reads separately
Anthropic’s prompt-caching documentation describes reuse of matching prompt prefixes. A cache hit can reduce processing cost and latency while the prefix remains part of the model’s context. It does not turn irrelevant context into useful evidence or authorize reuse across customers.
The earlier tracer is intentionally simplified. A production cost event should distinguish uncached input, cache writes, cache reads, output and any separately billed reasoning or tool usage. Reconcile the estimate with the provider’s usage record. Cache eligibility, lifetimes and rates vary by provider; check the current documentation rather than treating one token rate as universal.
Check yourself
A new cache lowers the inference bill, but stale policy answers increase. Is that a successful optimization? Only if the quality requirements still pass. Test freshness and invalidation alongside savings. Conor’s bad-context essay connects oversized inputs to wasted work; agent evaluation gives you the outcome checks that keep a cost cut honest.
Hear it from the guest
“I don't remember exactly, but it could have been like a quarter million dollars a month on just that summarization task.”
“Usually we start by expensive, the best. And then if the feature is successful, how can we optimize? How can we drive the cost down?”
“For an actual virtual assistant thing, I don't know the exact numbers but the LLM cost was about at least half of the operational overhead.”
“And it's actually price per token might eventually become a vanity metric because you might have the price per token go down, but the amount of tokens that an agent uses go up because they're long running agents.”
Quotes lightly edited to remove filler words.
Go deeper
- Prompt caching Explains cached prefixes, cache writes and hits; check your provider’s actual usage and pricing rather than assuming a cache makes tokens free.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
Concepts in this explainer
AI GatewayBatch InferenceCost per PRCost per TaskLong-Running AgentModel RoutingPrefill and DecodePrompt Caching