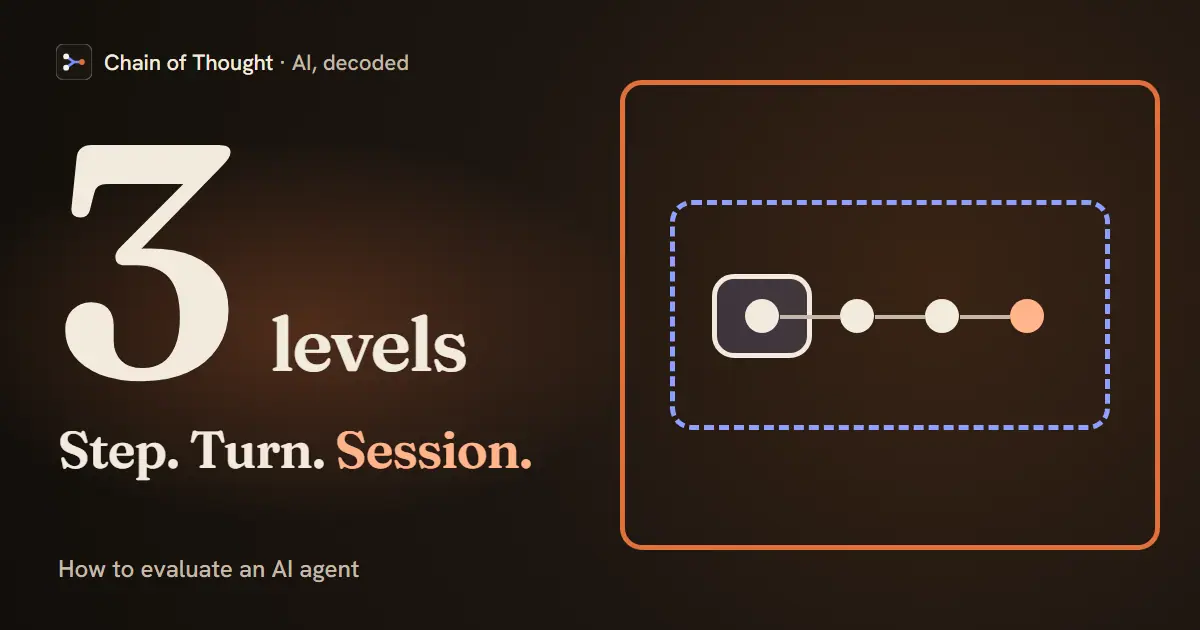
In detail
These three levels come from Conor’s framing in episode 5 at 6:00, describing how builders evaluate agentic workflows at the step, turn and session level.
1. Step level: did it choose the right tool?
At each individual point in the workflow, did the agent pick the correct tool and use it correctly, with the right parameters. A lot of agent failures start here: it calls the wrong tool, or the right tool the wrong way.
2. Turn level: did it do the steps in the right order?
Zoom out one level. Were necessary dependencies respected so the workflow could reach the right result? An agent can make every individual call correctly and still fail because it did them out of order or looped without stopping.
3. Session level: was the final result actually right?
The whole workflow, end to end. Did the agent deliver the outcome the user actually wanted. This is the one that matters to the person using it, and the one a step-level score can completely miss.
The trap to avoid
Chip Huyen’s warning in episode 5 at 28:00, drawn from a LinkedIn case study: a “correct” answer is not always a “good” answer. A job-fit bot that tells a candidate “you’re a terrible fit” can be technically correct and still not a good answer. So evaluating an agent is less about one number and more about defining, at each level, what good actually looks like for your use case.
Why it matters
Use step, turn and session checks to locate failures, and verify the final outcome separately. A single score cannot tell you which constraint failed.
Work backward from the state the user needs
Anthropic’s agent-evaluation guide distinguishes a trace from an outcome. An agent can say it booked a flight while no reservation exists. Step and turn checks explain a failure; the final state establishes whether the task succeeded. Avoid requiring one exact tool sequence when several authorized sequences reach the same valid result.
Worked example, with invented records: a support agent may refund one eligible order, once, after verifying the customer. The following checks belong in the evaluation before the agent sees the task.
| Check | Passing evidence | A failure it catches |
|---|---|---|
| Outcome | The ledger contains the correct refund for that order | The assistant says “done” without a refund |
| Authorization | The requesting customer owns the order | A correct refund issued to the wrong account |
| Side effects | No duplicate refund and no unrelated record changed | A timeout followed by a second payment |
| Interaction | The reply accurately explains the recorded result | A reassuring answer that conceals failure |
Run each case repeatedly from a reset test environment. Record success frequency, unsafe-action attempts, cost and latency. Keep the outcome check separate from the explanation score: good prose cannot cancel a forbidden action. These are our suggested checks, not measurements from the episode.
Check yourself
A run uses a different valid tool sequence, reaches the right ledger state and respects the permission boundary. Should it fail because its trace differs from a reference trace? Usually no. Fail it for violating a necessary constraint, rather than for finding another valid route. Continue with testing properties and deterministic boundaries and metrics beyond accuracy.
Disclosure: Episode 5 aired while Chain of Thought was Galileo’s podcast and Conor worked there; the step, turn and session framing is his from that time.
Try the tradeoff yourself: inspect two signals from an agent’s patch, then make the release decision.
Hear it from the guest
“The other is whether it can call the right tool. So a lot of time, we'll try to call like an invalid tool. Or it will try to use the correct tool, but not with the right parameter.”
“For example, if the candidate asked the bot like, Hey, am I a good fit for this role, the bot would respond, No, you're a terrible fit. So it is a correct response, but it's not a good.”
“This agent evaluation is a superset of LLM evals that we had in the past plus all the consequences for tool calling that is coming to the picture.”
“Just imagine like a standardized test, like the SAT or something. That's where we were like a year or two ago, like multiple choice questions, right?”
“One mistake in any part of this workflow can lead to massive, errors downstream. The errors kind of compound.”
Quotes lightly edited to remove filler words.
Go deeper
- Demystifying evals for AI agents Separates the agent trace from the final environment state and explains repeated trials.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
Concepts in this explainer
AI EvaluationAgent TrajectoryCross-Model ReviewEval-Driven DevelopmentLLM as a JudgeModel DriftReward HackingTask Success Rate