In detail
Start with the outcome, then the spend
Most teams can’t measure payoff because they never named the outcome. Jiaona Zhang, CPO at Laurel, puts the first step as visibility: “how do you get visibility in terms of your spend versus the outcomes that you’re actually trying to drive?” (5:03) Two outcomes qualify. Revenue, or time-allocation efficiency. Pick one before you count tokens. In her words, “one of the big things that people aren’t doing enough of is taking the time to even articulate what that is.” Spend has nothing to measure against until the outcome is stated.
Update, October 3, 2026: Automating a process can preserve the bottleneck it already had. In episode 71, Jaime DeLanghe warns that faster coding agents still face the same cross-team checks unless the organization changes how those checks work. DeLanghe describes successful approaches as outcomes-based, then contrasts the responsibility to deliver useful products with writing product-requirements documents faster. For this article’s measurement question, that suggests checking whether faster documents advance the intended outcome.
Count time back
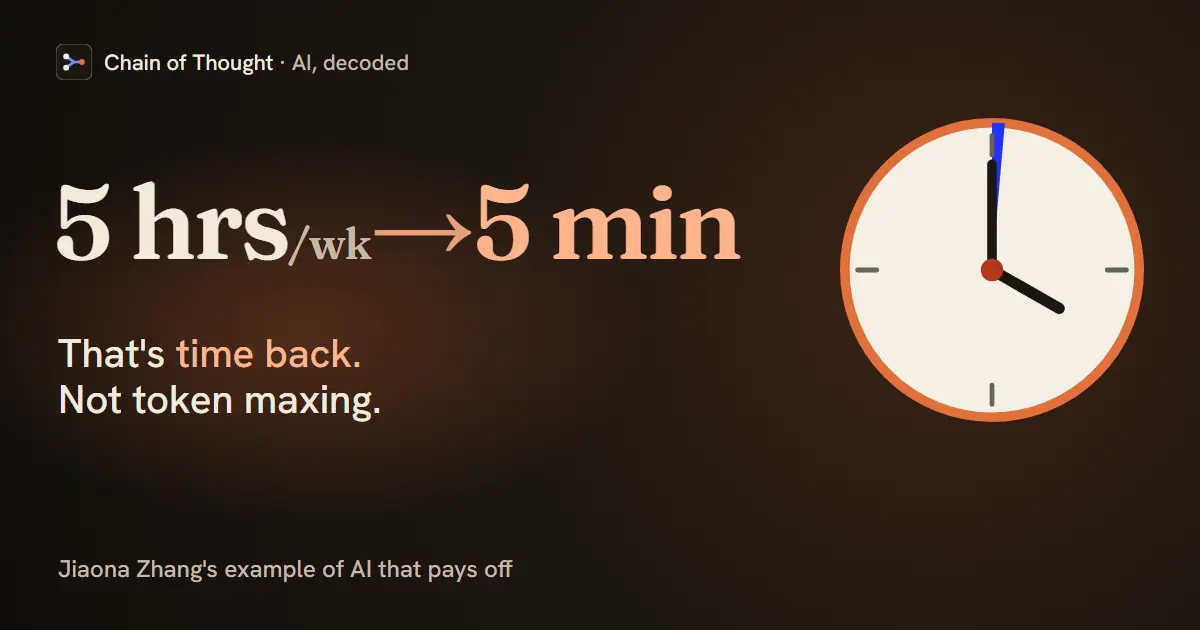
A mandate to use AI everywhere, tied to performance reviews, produces usage theater. People reach for AI to prove they used it. Zhang’s name for this is “token maxing,” and her measure of what went wrong is sharp: the yardstick becomes “are you just doing it versus are you using it efficiently.” (4:05) Her example of the wrong kind is redoing the font on a deck with AI “when you could have just clicked a button.” The unit that counts is time back: work that “took humans five hours per week” (0:00) and “an agent did in five minutes.” Measure the efficiency of the token spend, not the fact of it.
Read cost per PR with context
A unit metric can still mislead. In episode 76 at 4:06, Sonar CTO Andrea Malagodi describes the industry moving toward cost per PR, meaning AI spend divided by the pull requests it produced. When his team ran the numbers (4:33), the extremes were two engineers. One opened over 500 PRs in a short period at a low cost per PR. The other spent heavily and produced very few.
A pure FinOps reading says keep the first and question the second. Malagodi found they were doing different work. The high-volume engineer had built a staged software factory of agents, and almost two-thirds of the output was tests and validation (5:29–6:37). The other engineer’s problems needed long, deep AI analysis that didn’t turn directly into lines of code (7:20). His advice at 7:57 is to keep the numbers but not judge them before you understand the problem behind them. That’s the same test as above: compare spend with the outcome the work was meant to drive. Episode 76 names Svix, Walrus Memory and Inngest as the season’s presenting sponsors; the Svix read is at 14:55.
Map the ontology of work
Zhang’s method for finding where AI pays off runs in two directions at once. Bottom-up: ask a person for the one workflow they most wish they didn’t have to do, automate it, and let the relief do the convincing. Top-down: “you have to understand your ontology of work,” (28:30) the buckets that make up each function, then “in mass try to automate this whole chunk.” (30:23) You measure the automated chunk against the time it used to consume. Laurel’s own desktop agent captures how people spend time across applications, so a team can see whether someone sits on “high leverage work” or “low leverage work that could be automated.” (5:03)
Where this fits
Enterprise projects that fail to show ROI usually fail for operational reasons covered in the companion question: unbudgeted production costs and success metrics that were never defined. This is the measurement itself. Name the outcome, price it in time or revenue, and check the token spend against it. A project that removes five hours of weekly drudgery produces a number a leader can point to. A project that only proves AI was used produces activity. The price of a given level of capability keeps falling, by about 47% a quarter on Epoch AI’s estimate, but agents and reasoning models burn more tokens per task, so total spend can still climb. That makes the question of where the spend earns its return more pointed from here.
Hear it from the guest
“If you use AI to go like redo the font on this deck when you could have just clicked a button, that is not an efficient use of your tokens. But if you used AI and you took something that took … humans five hours per week, and you took that and agent did in five minutes, that is time back, right?”
“What is it that you're really trying to drive? And I think one of the big things that people aren't doing enough of is taking the time to even articulate what that is.”
“Don't just assume that having faster coding agents is going to solve that problem.”
“Is my application with this model doing what I expected it to, but it's actually moving a business metric we care about.”
“So yes, it's good to have numbers. … and we should be very careful to not pass … judgment too quickly.”
Quotes lightly edited to remove filler words.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
Concepts in this explainer
Cost per PRToken MaxxingA/B TestingAutomationCost per TaskToken PricingSoftware FactoryCoding Agent