In detail
Both power retrieval-augmented generation — giving a model the right context at answer time — but they retrieve on different principles. The choice follows the shape of your data and your tolerance for a confidently wrong answer.
1. Vector databases retrieve by meaning
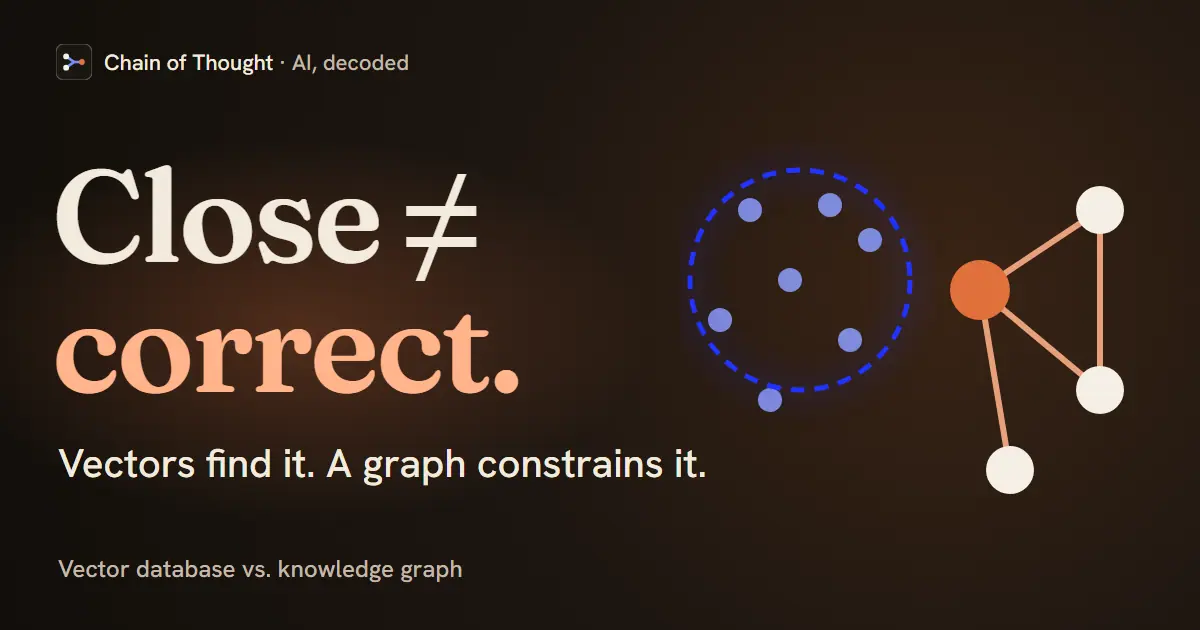
A vector database stores text as embeddings and finds passages whose meaning is closest to the query, even with no shared keywords. Weaviate’s Bob van Luijt says large-scale search, mostly hybrid search, was the first thing his customers took to production: it’s a fast way to make a large pile of unstructured documents searchable by intent. Where it’s weak is precision on facts — “close in meaning” can surface a passage that’s relevant but not correct.
2. Knowledge graphs retrieve by relationship
A knowledge graph stores entities and the explicit links between them — facts, hierarchies, who-relates-to-what. On the show, Neo4j’s Sudhir Hasbe argues that hallucination is a data-architecture problem: when answers must respect real relationships and constraints, a graph gives the model grounded, structured facts instead of fuzzy nearest neighbors. The cost is that you have to model and maintain that structure.
3. The pattern is “and,” not “or”
The strongest setups use both — often called GraphRAG. Vectors cast a wide net to find the relevant neighborhood; the graph then constrains and enriches it with the exact entities and relationships that make the answer factual. Vectors handle recall over messy text; the graph handles precision over facts.
How to choose
Mostly unstructured text, relevance by topic, speed to stand up → vector database. Answers that hinge on explicit relationships, compliance, or traceable facts → knowledge graph. Hallucination is biting and your domain has real structure → combine them.
Why it matters
Picking one because it’s the default — usually the vector database — leaves precision on the table for problems that are really about relationships. Let the data decide: meaning-similarity and fact-structure are different jobs, and the best retrieval stacks do both.
Hear it from the guest
“You may be listening to a pop song and suddenly the next vector similarity could show you in country music or some other music genre. Because in vector space, it's just mathematical similarities that you're looking at.”
“When I say graph RAG, it is a combination of, I can do a vector search, And then I'm applying a filtering layer with all the other metadata as a graph layer on top of it.”
Quotes lightly edited to remove filler words.
Go deeper
- Getting started with Faiss Trace nearest-neighbor IDs and squared distances in a flat L2 index. The example uses synthetic vectors, not text embeddings; running it needs Faiss and Python/NumPy or C++.
- MATCH patterns in Cypher Compare the distance-based shortlist with explicit relationship patterns and returned rows. Running the examples needs a sample Neo4j database; stored relationships still need accurate source data.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
Concepts in this explainer
Knowledge GraphVector DatabaseGraphRAGSemantic SearchEmbeddingsRetrieval-Augmented Generation (RAG)AI HallucinationAccuracy