In detail
Traditional RAG: one shot at retrieval
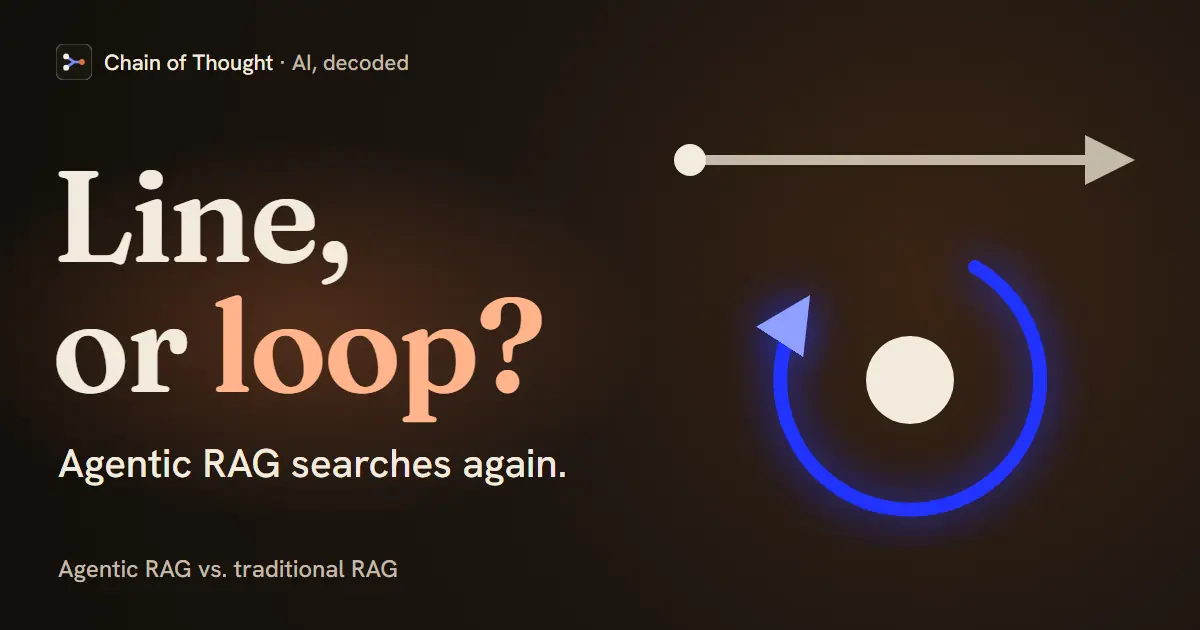
Classic retrieval-augmented generation is a straight line. A query comes in, an embedding search returns the closest chunks, and the model answers using whatever came back. It is fast and cheap, and it works well when the answer lives in one obvious place. Its weakness is that it never second-guesses the retrieval. If the first search misses, the model answers from bad context and you get a confident wrong answer.
The term comes from Lewis et al. (2020), which paired a pre-trained language model with a dense vector index of Wikipedia accessed through a neural retriever. Weaviate co-founder Bob van Luijt described the production version in episode 8 at 6:03: a query retrieves documents, they go to the generative model, and the answer goes to the user. “That’s one directional.”
Agentic RAG: retrieval as a decision
Agentic RAG wraps retrieval in an agent’s reasoning loop. The agent can decide whether a question even needs a lookup, rewrite a vague query into a better one, query several stores or tools, and grade the results before answering. If the context is thin, it retrieves again with a different approach. Retrieval stops being a fixed step and becomes a series of decisions the agent makes toward an answer.
Two research designs make those decisions explicit. Self-RAG trains a model to retrieve passages on demand rather than every time, and to critique both the passages and its own output. Corrective RAG adds a lightweight evaluator that scores the retrieved documents and triggers different actions depending on its confidence, including a web search when the static corpus falls short. In episode 2 at 16:49, van Luijt put the practical case: one-directional RAG “brought us very far,” but questions that need multiple queries or sources need loops.
When the trade-off is worth it
The loop costs more — more model calls, more latency, more that can go wrong. For simple lookups, plain RAG wins. Agentic RAG earns its keep on multi-part questions, sources that need to be combined, and cases where a wrong answer is expensive enough to justify the extra checking. Databricks’ Craig Wiley described that shift in episode 3 at 14:00: during 2024, teams found that “prompt plus some docs doesn’t equal a system that I can bet my company’s reputation on,” and the systems run at production quality are often compound or agentic.
Decide what another retrieval step would fix
Use these suggested checks on your own workload before adding a retrieval loop. They are a decision aid, not benchmark results from the episodes.
| What your cases show | Start with | Evidence to collect |
|---|---|---|
| One search consistently returns the passages needed to answer | A fixed retrieval pipeline | Correct answers and missed passages on a labeled set of questions |
| The first result reveals a necessary follow-up question | A bounded retrieval loop | Whether the extra search supplies the missing evidence and changes the answer correctly |
| The authoritative answer is absent from every connected source | An abstention or escalation path | Answerable and unanswerable cases, so refusing everything cannot pass |
| Extra searches improve some answers but exceed the time or cost budget | A comparison with the fixed pipeline | Quality, elapsed time and total cost per verified answer, including retries |
Set a stopping rule before the loop runs: a call budget, a deadline and a response when the evidence remains insufficient. More retrieval attempts do not establish that the final answer is grounded. Check the retrieved passages and the answer separately using the RAG evaluation procedure.
Disclosure: Episodes 2, 3 and 8 were recorded while Conor worked at Galileo; episode 8 includes a Galileo ad read at 22:30.
Hear it from the guest
“So it is like you have a query, you retrieve some potential, documents, you send them to the generative model and you present it to the end user. That's one directional.”
“It's brought us very far, but now we need to start to bring in loops, right? So what if you have more questions? What if we need to query multiple times?”
“Prompt plus some docs doesn't equal a system that I can bet my company's reputation on.”
Quotes lightly edited to remove filler words.
Go deeper
- Self-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection Trace when the trained model requests retrieval and emits reflection tokens. This is a learned method, rather than a prompt-only retry recipe; the paper is a reading task.
- Corrective Retrieval Augmented Generation Compare an evaluator's refinement, web-search and combined actions with Self-RAG's learned decisions. Inspect the fine-tuned evaluator requirement and its errors before adopting the design.
- Agentic RAG Systems: Integration of Retrieval and Generation in AI Architectures Compare Conor's earlier overview of query reformulation and repeated retrieval with the stopping rule, cost and evidence checks above.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
Concepts in this explainer
Retrieval-Augmented Generation (RAG)Agentic RAGGraphRAGAI BenchmarkGenerative AILatency