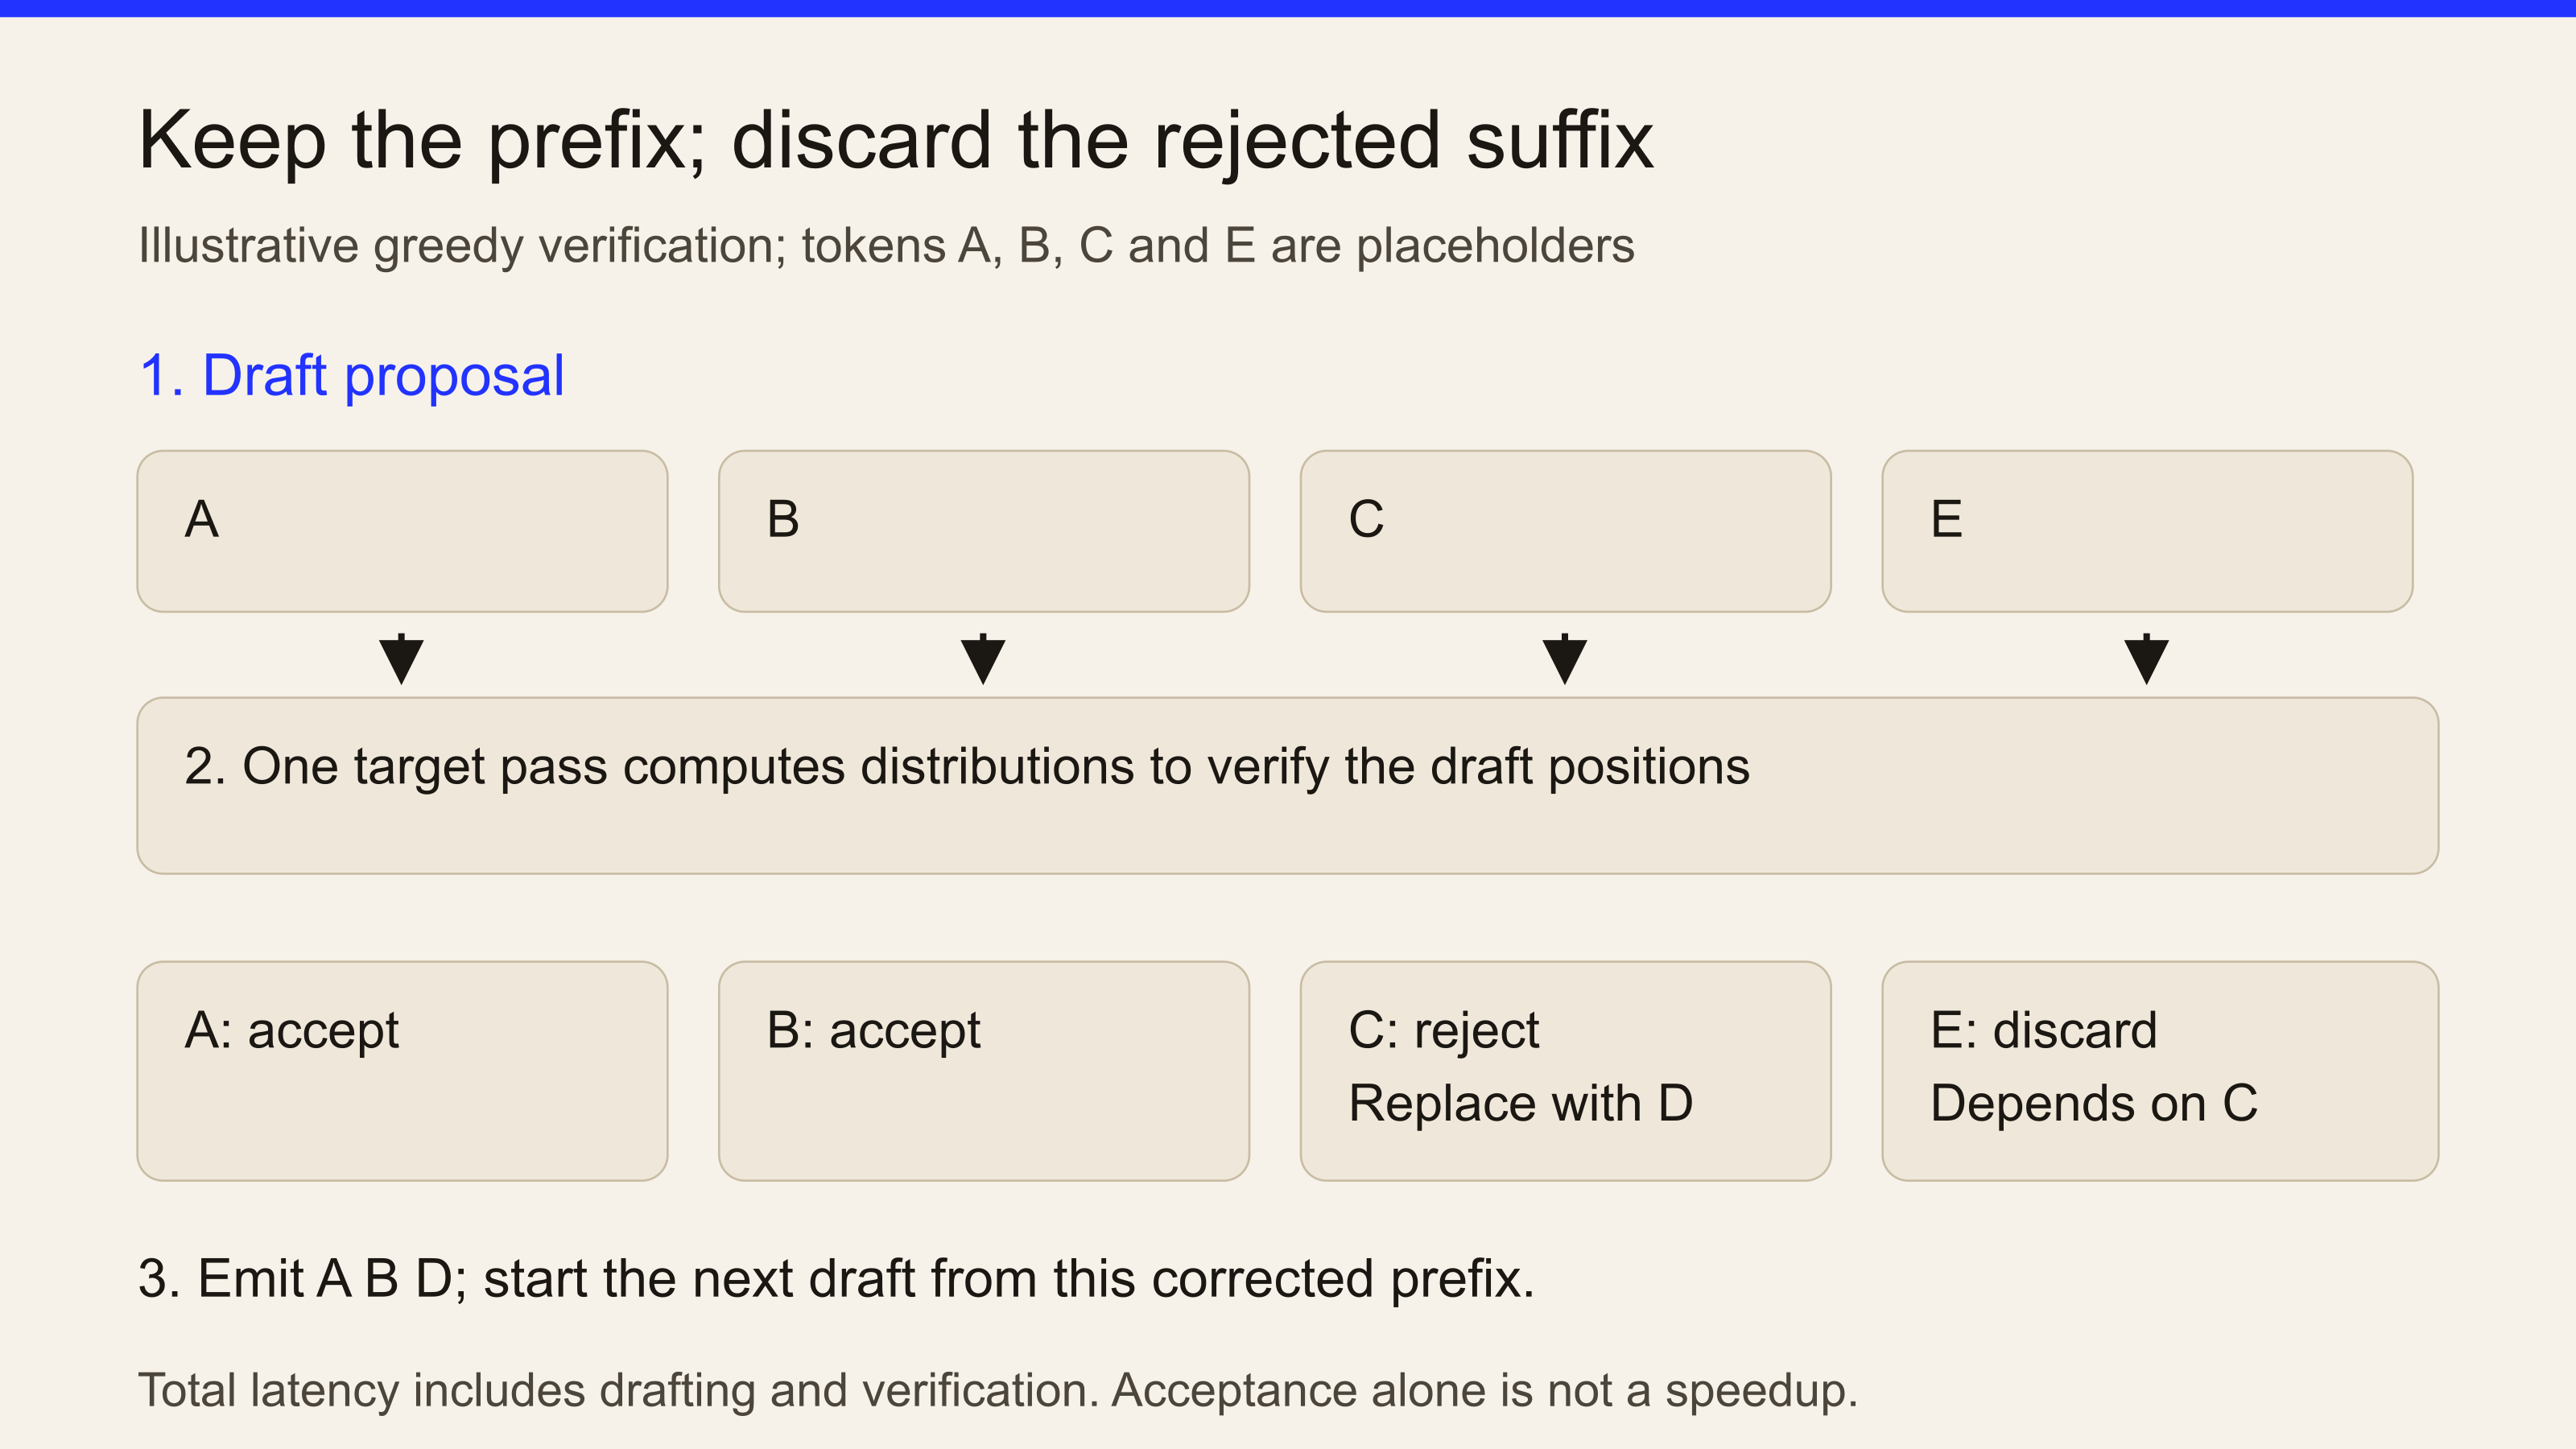
A draft model proposes a short continuation. The target model computes the distributions needed to verify those positions in one pass. The procedure accepts a prefix; at the first rejection it discards the rejected token and everything after it, then generates a replacement. Later proposals depend on the rejected context and cannot simply be kept.
For example, in greedy decoding the draft proposes A, B, C. If A and B match the target’s choices but C does not, keep A and B and use the target’s choice D at that position. This illustrates greedy verification, not the stochastic acceptance rule. The original exact sampling algorithm uses probability-based acceptance and a corrected replacement distribution to preserve the target’s sampling distribution.
Measure total runtime, including drafting and verification. Low acceptance or extra overhead can erase a speedup. Speculation changes the computation path; it does not improve the target’s evidence or spend test-time compute exploring better answers.
Sources
- Leviathan et al.: Fast Inference from Transformers via Speculative Decoding — Gives prefix acceptance, corrected replacement sampling and the distribution-preservation result for the exact algorithm.
Go deeper
- vLLM: Speculative decoding docs
Inspect serving configurations and limits for draft-based decoding in a concrete engine.
- Chen et al.: Accelerating Large Language Model Decoding with Speculative Sampling paper
Compare modified rejection sampling with greedy verification, and examine the conditions behind the paper's target-distribution and speedup results.