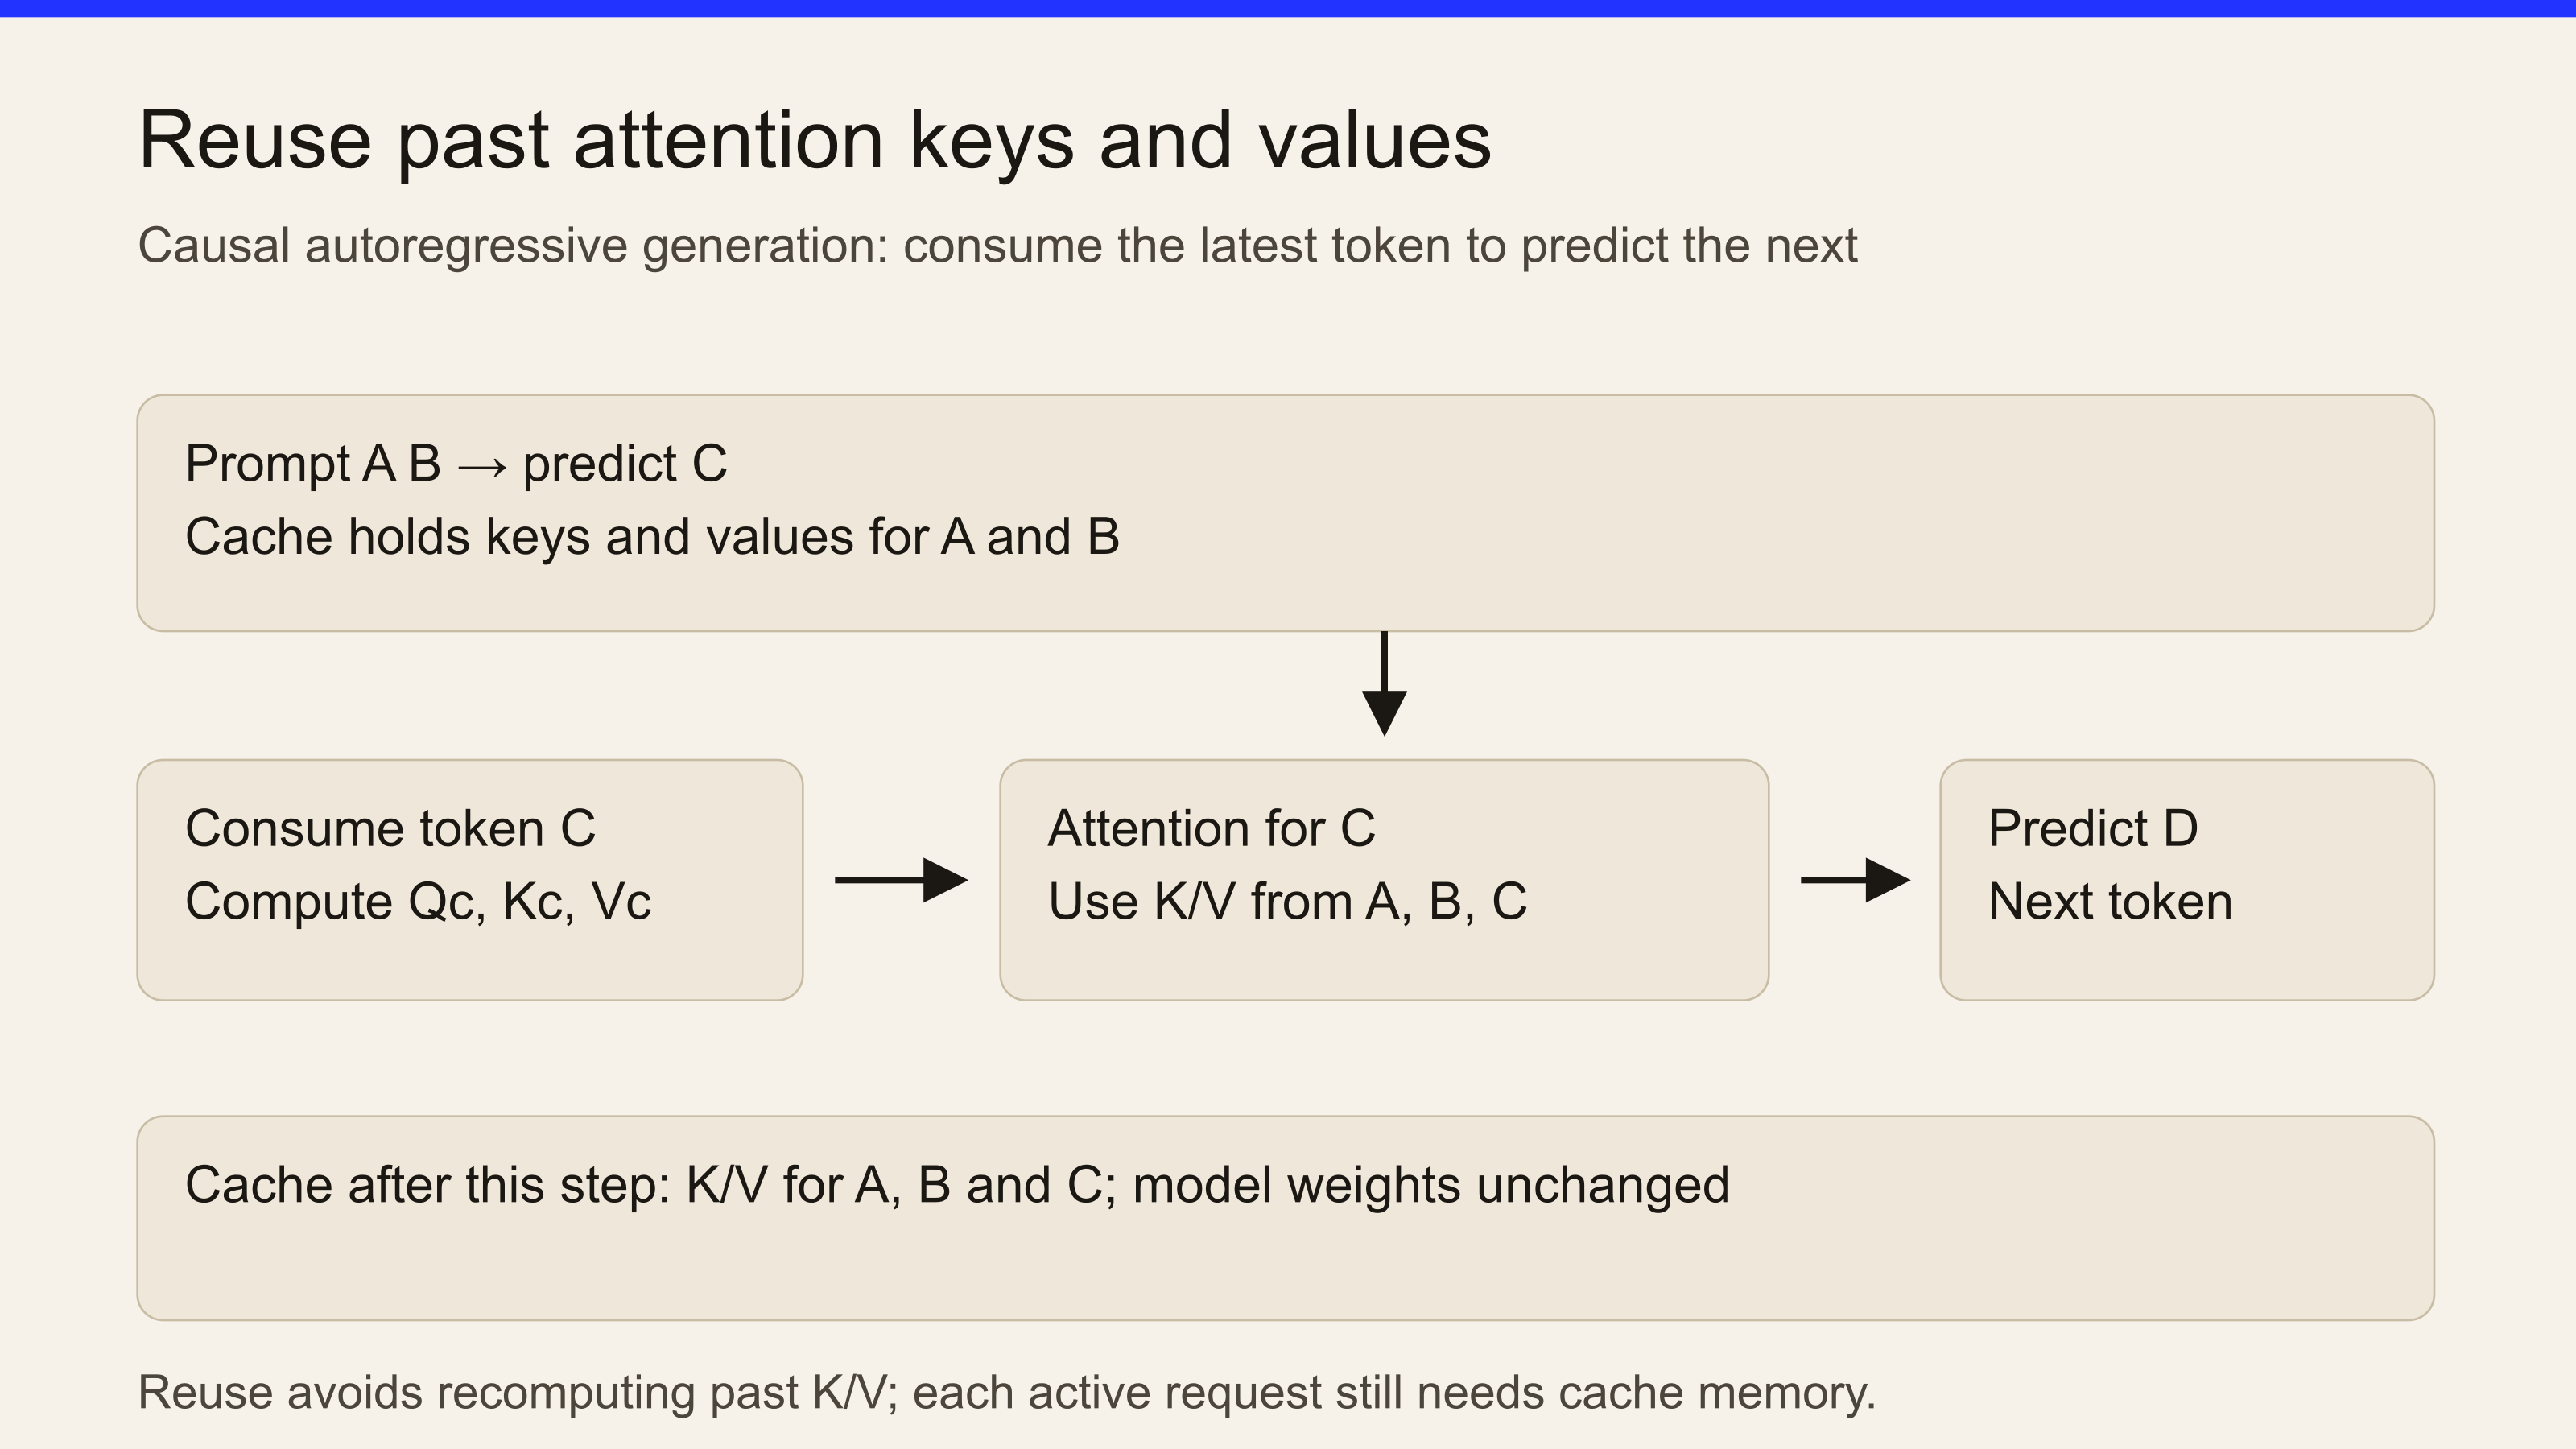
When a transformer produces another token, it needs information about earlier tokens. Keeping their attention keys and values avoids recomputing that state from scratch. This is runtime state, distinct from the model’s trained weights and from an agent’s persistent memory.
Example: a model’s weights may fit on a GPU, but serving many long conversations can still exhaust its memory because each active request needs cache space. Model architecture, context length, precision, and concurrency all affect that footprint.
Liquid AI’s Maxime Labonne discusses this tradeoff in episode 43, at 3:08: his account compares memory use, inference speed, and quality across architectures. That is a concrete reason to benchmark your serving workload rather than compare parameter counts alone. Cache quantization or offloading can change memory use, with their own quality or performance tradeoffs.
Sources
- Hugging Face: Cache strategies — Explains attention-state caching and memory/performance choices.
Go deeper
- Are small language models better than large ones for production? AI, decoded · Small Language Models in Production
- Why is it so hard to move AI workloads off NVIDIA? AI, decoded · The Switching Cost in AI Hardware Is Software
- Hugging Face: How caching works docs
Follow how attention appends new keys and values while reusing earlier token state.
- Kwon et al.: Efficient Memory Management for Large Language Model Serving with PagedAttention paper
Study how paging and sharing address KV-cache fragmentation in a serving engine; compare the paper's workload with your own before using its throughput results.