Keep initial retrieval and reranking distinct
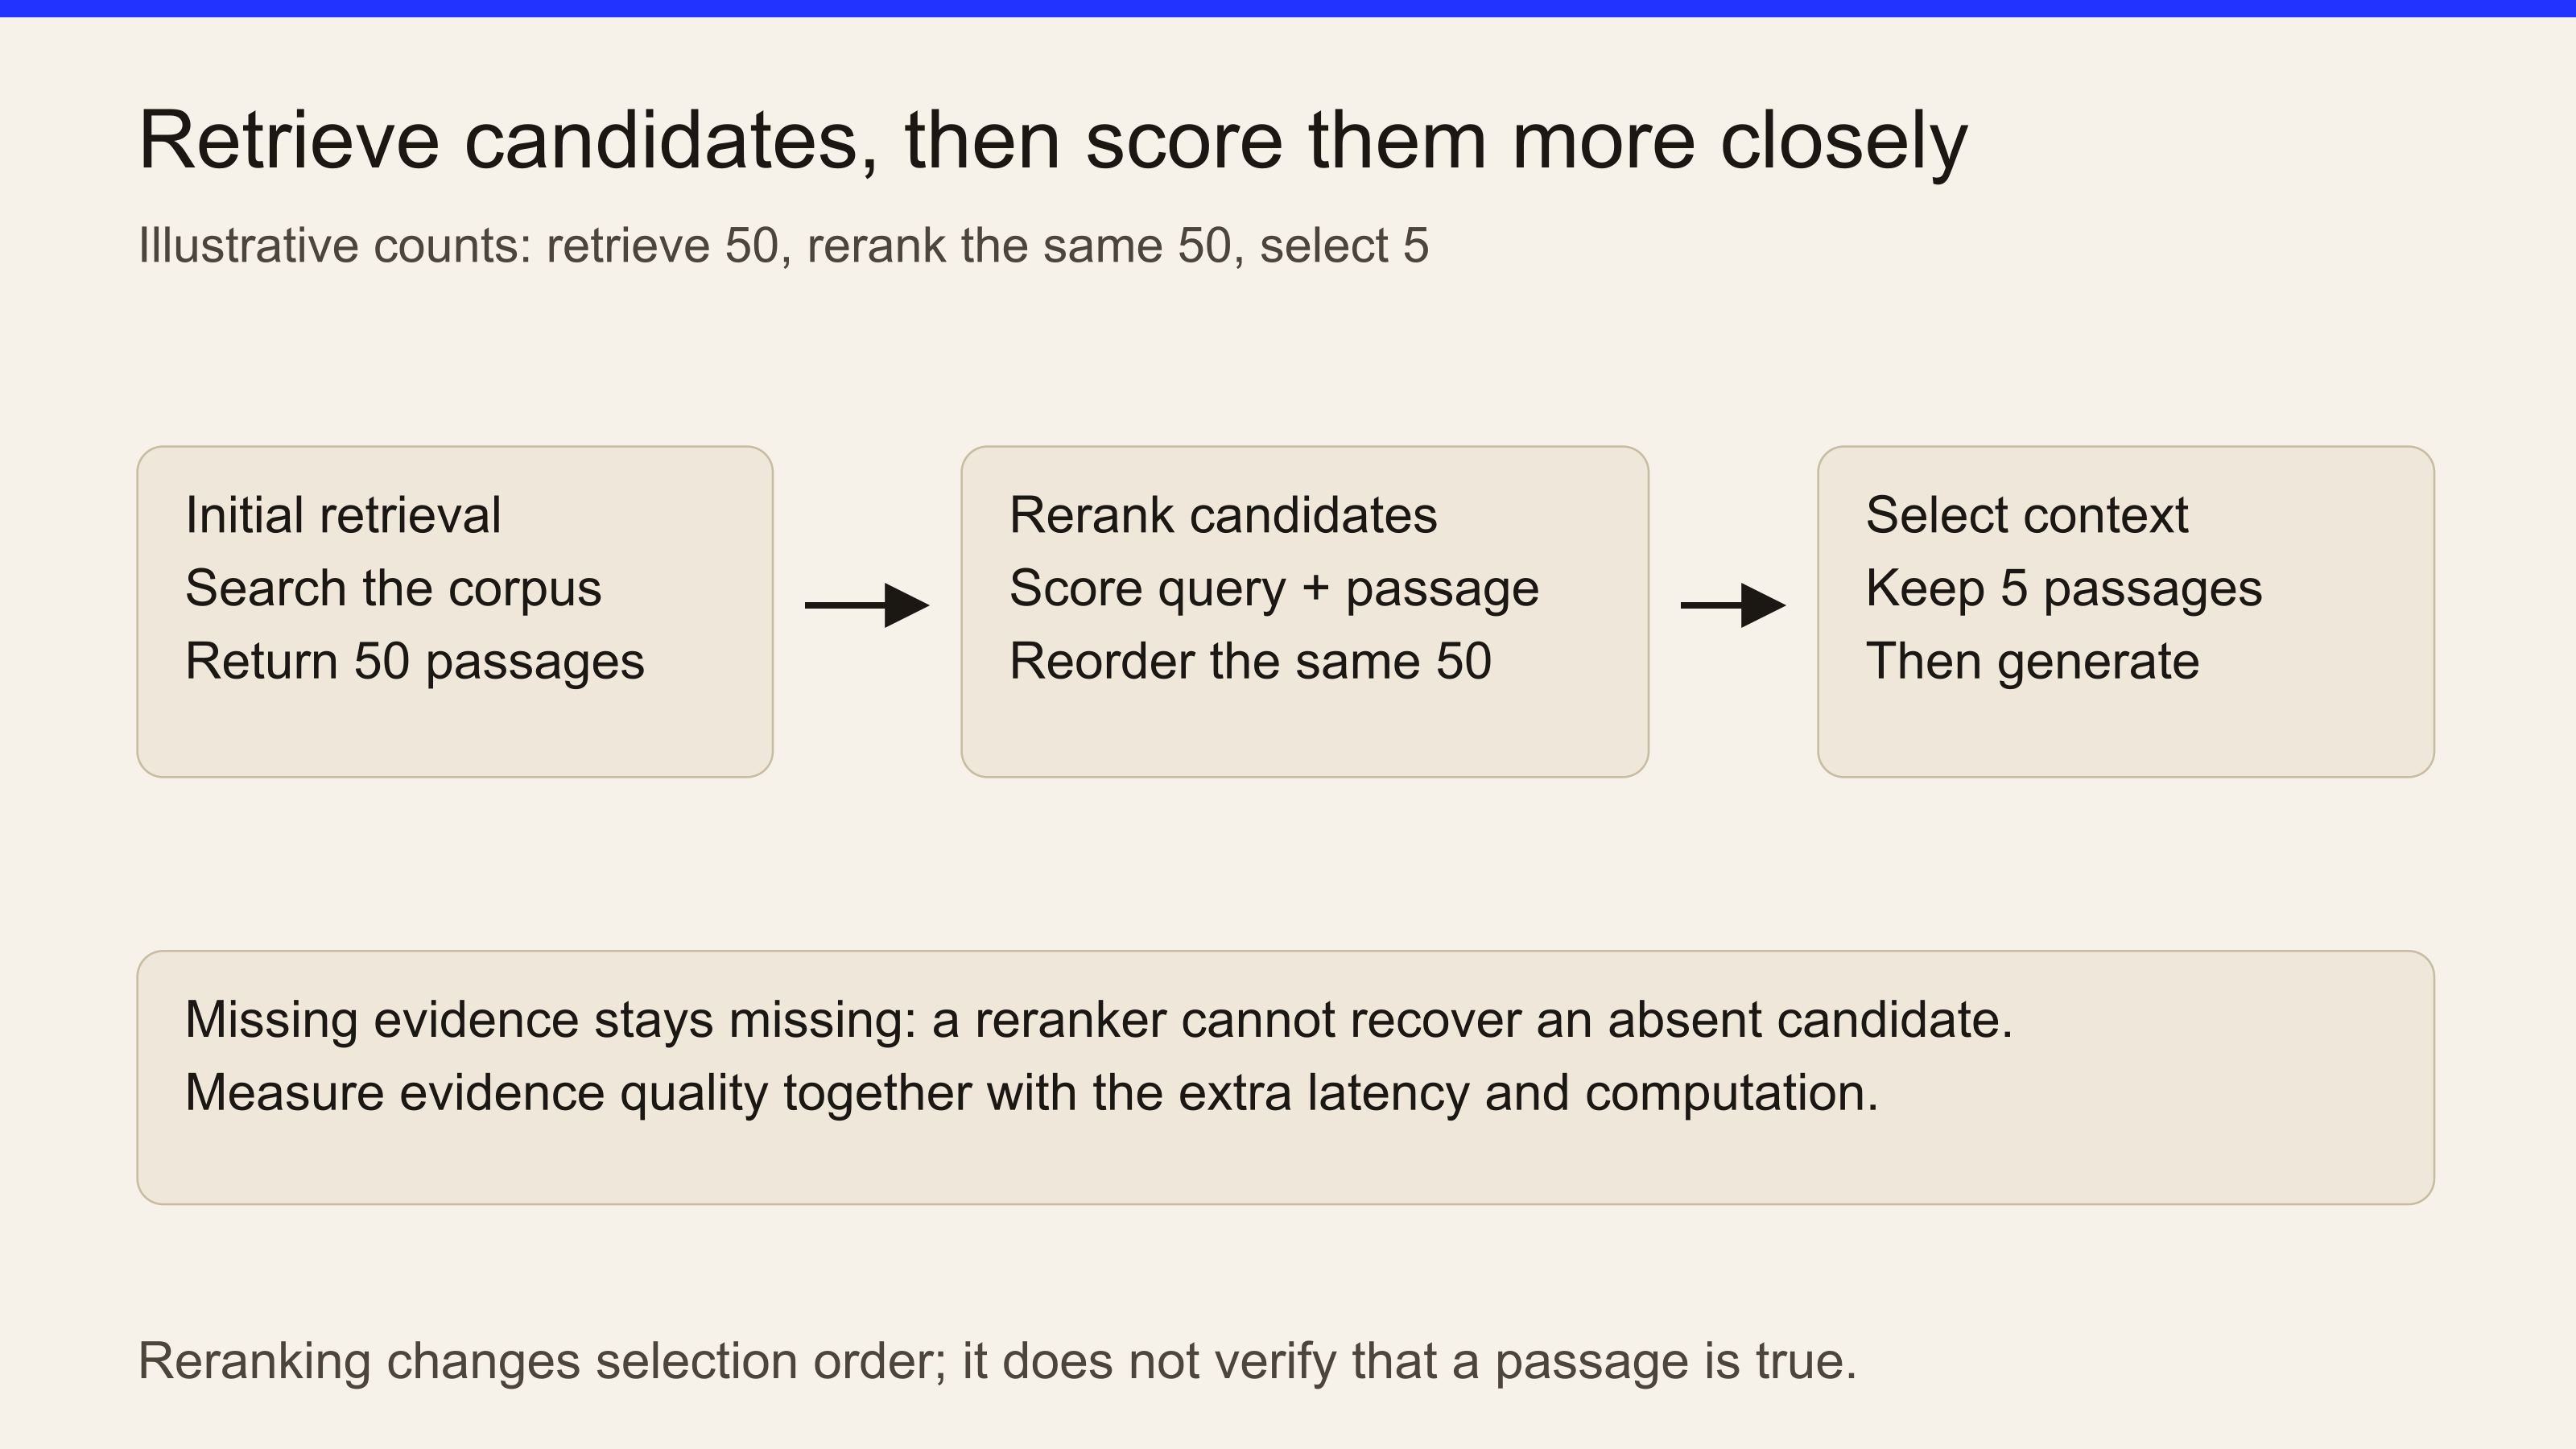
Initial retrieval searches the corpus for candidates. Sentence Transformers describes a second stage that scores the query and each candidate together with a cross-encoder. Other scoring models can fill this role; the reranker need not be the model that writes the answer. A reranker cannot recover a passage absent from its input set.
This differs from hybrid search, which combines retrieval paths, and from chunking, which determines the passages available to retrieve. Inspect those inputs before attributing every miss to the reranker.
Map results back to the submitted passages
Invented policy example: the question requires a deadline and its exception. Submit A, a wrong-product policy; B, the applicable deadline; and C, its exception. Suppose reranking puts B first, C second and A third.
| Passage | Input index | New rank |
|---|---|---|
| A | 0 | 3 |
| B | 1 | 1 |
| C | 2 | 2 |
Cohere’s Rerank documentation uses zero-based result indexes into the submitted document list. In that convention, index 1 identifies B even when B is ranked first; it does not identify the second item in the new ranking. Preserve source IDs when mapping returned results into context. Check other interfaces’ conventions rather than assuming they use the same fields.
The first two candidates before reranking are A and B; the first two afterward are B and C. Both required clauses are now available. But if final context assembly keeps only the first passage, C is lost again. If initial retrieval omitted C entirely, reordering A and B cannot supply the missing exception. What matters is whether the passages that reach the model support the whole answer.
Measure the context and the completed answer
In episode 49 at 15:04, Fergal Reid describes Intercom’s work on retrieval and a custom reranker among the systems surrounding its answer model.
Hold the corpus, first-stage candidates and relevance judgments fixed when testing a reranker change. Then inspect the passages that survive the actual cutoff and context budget, with source IDs and required qualifications intact. Test duplicated passages and a candidate set missing the exception as well as the complete case. Scoring more candidates adds work; reducing downstream context can change the full request’s cost and waiting time. Measure the complete path instead of assuming reranking always speeds it up.
The RAG evaluation guide separates retrieval and answer checks. The response-latency guide follows the user’s broader waiting path; a better ordering alone is not a useful completed answer.
Sources
- Cohere: Rerank overview — Describes a query plus submitted documents and result indexes pointing back into that input list, starting at zero; those indexes are not the new ranks; checked November 2, 2026.
- Sentence Transformers: Retrieve and re-rank — Explains candidate retrieval followed by cross-encoder query/passage scoring; checked November 2, 2026.
Go deeper
- How do you evaluate a RAG system? AI, decoded · How to Evaluate a RAG System
- How do you make an AI feature respond faster? AI, decoded · How to Reduce AI Response Latency
- What is RAG, and why do AI systems use it? AI, decoded · What Is RAG (Retrieval-Augmented Generation)
- What is a reranker in a RAG system? AI, decoded · What Is a Reranker in RAG?