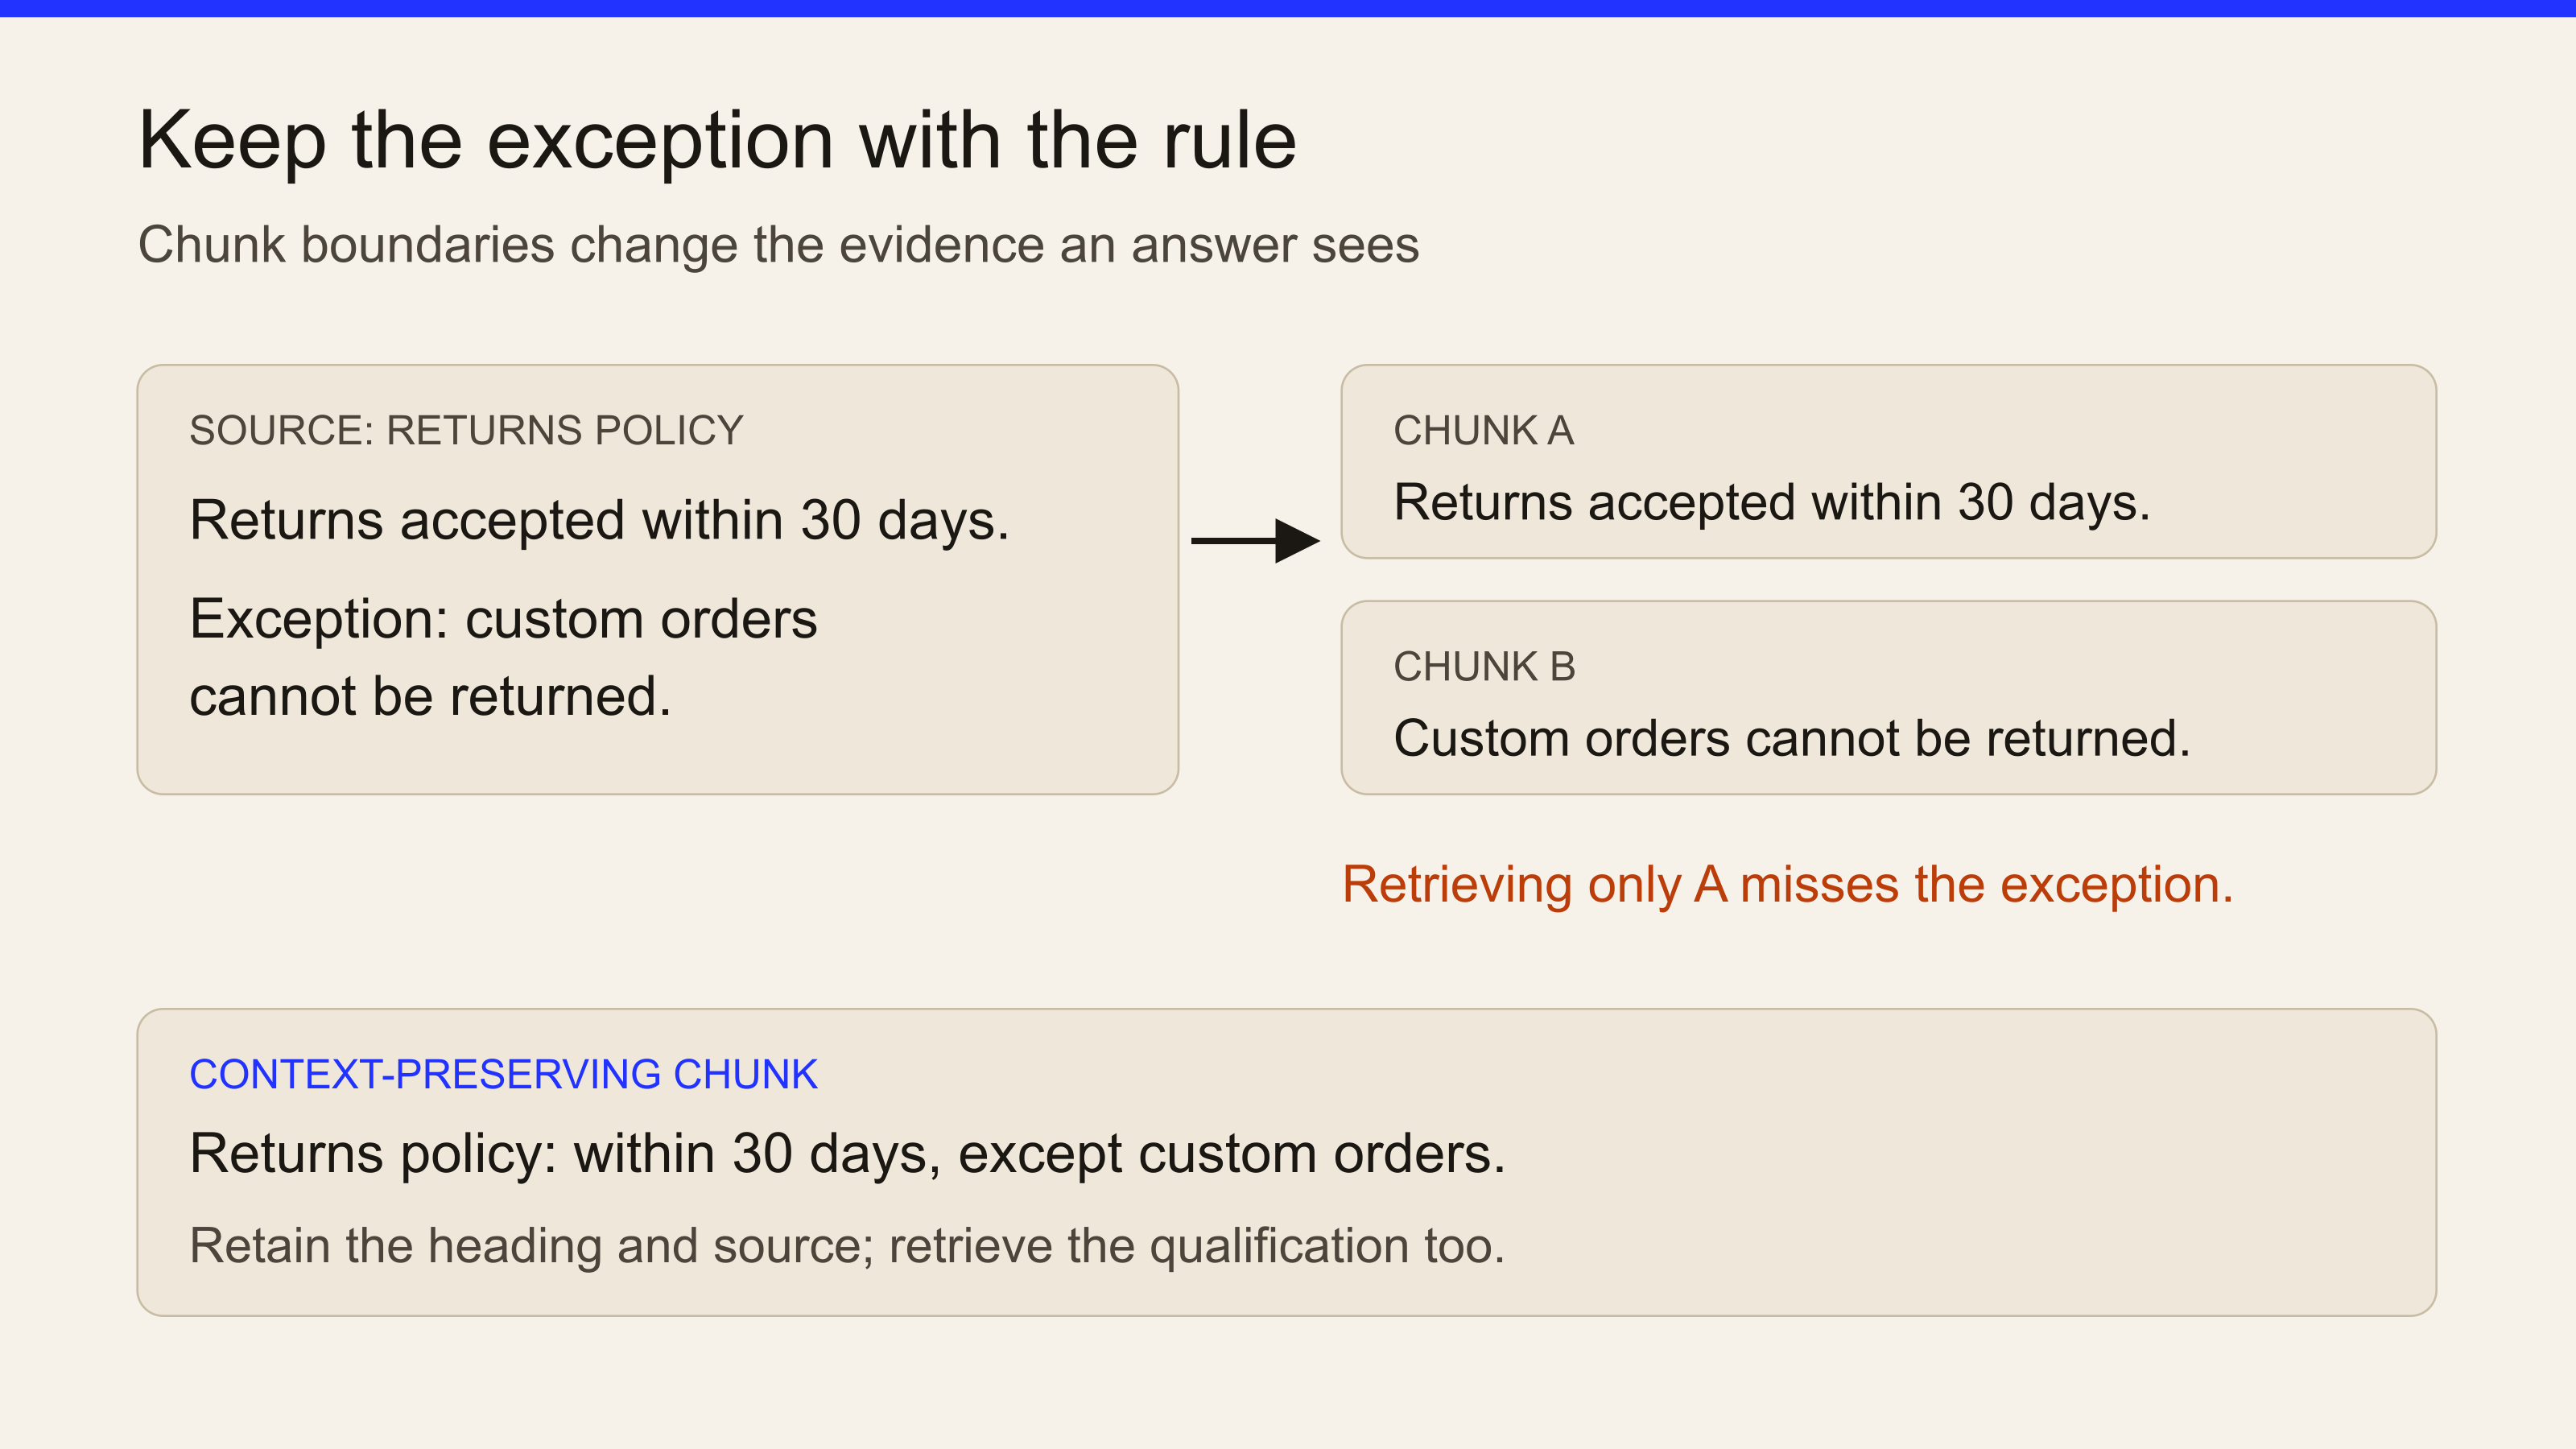
Consider a returns policy with a general 30-day rule and an exception for custom orders. If the exception lands in a separate chunk, a search can find the general rule and miss the qualification. Keep the rule and its relevant exception together, or give retrieval a way to return both.
A chunk saying “the limit is 30 days” also needs the product or customer tier named by its heading. Preserve useful headings and source identifiers with the text. Anthropic’s Contextual Retrieval approach addresses this loss of context by adding a short explanation of each chunk’s place in the document before indexing it. Check any generated explanation against the source and keep it distinguishable from the verbatim text; added context can be wrong too.
There is no universal best size. Small chunks can retrieve a precise passage but omit context; large ones can include the context but also unrelated text. Overlap can protect boundaries at the cost of duplicates. Test representative questions and inspect whether their supporting evidence survives the split, using retrieval evaluation.
Count overlap in the units your splitter uses
A splitter’s size and overlap settings are counted in whatever unit its length function measures. LangChain’s recursive splitter example passes length_function=len, which counts Python string characters, not model tokens, and its documentation calls chunk_overlap a target overlap. Inspect the actual splits rather than assuming every neighboring pair shares exactly that amount.
Hand-worked example, not splitter output: split the ten characters ABCDEFGHIJ into two slices of six. Positions are one-based and inclusive.
| Slice | Text | Source positions |
|---|---|---|
| 1 | ABCDEF | 1–6 |
| 2 | EFGHIJ | 5–10 |
The two slices store 12 characters for 10 source characters. EF appears in both: the overlap repeats positions 5–6, it does not add new evidence. If both slices come back for one question, the repeated EF is not independent corroboration; the non-overlapping text can contain different information. Keep each chunk’s source ID and position, so repeated hits from overlapping chunks can be recognized as duplicates. These counts say nothing about model tokens or the right chunk size.
Sources
- Anthropic: Contextual Retrieval — Describes context lost by isolated chunks and the effects of size, boundaries and overlap.
- LangChain: Splitting recursively — Example uses Python len and describes overlap as a target; checked November 3, 2026.
Go deeper
- How do you evaluate a RAG system? AI, decoded · How to Evaluate a RAG System
- What is RAG, and why do AI systems use it? AI, decoded · What Is RAG (Retrieval-Augmented Generation)
- Docling: Structure-aware and token-aware chunking docs
Compare hierarchical boundaries with HybridChunker's token-aware splitting and merging. Inspect headings and table-header handling; implementation needs Python, Docling and a tokenizer.