Define the workload and a valid result
Triton’s autotune API evaluates candidate kernel configurations when specified key arguments change. It warns that evaluation runs the kernel repeatedly and provides reset/restore controls for values that repeated execution would otherwise modify. Record input shapes, precision, hardware and mutable state so candidates face comparable work.
A fast timing is not a correctness test. Define the reference output and acceptable numerical tolerance before comparing candidates. A setting that changes the result can be unusable even if it finishes sooner. Fine-tuning trains model parameters; searching runtime or kernel settings is a different operation.
Account for the time spent searching
Invented timings for identical serial calls, with no overlapping work:
| Configuration | Time per call | Correctness check |
|---|---|---|
| Baseline | 10 ms | Pass |
| Candidate B | 8 ms | Pass |
| Candidate C | 6 ms | Fail |
Candidate C is excluded despite its shorter time. Suppose the one-time tuning overhead is 12 seconds and B saves 2 milliseconds on each later call. The break-even point is 12,000 / 2 = 6,000 calls: baseline time is 60 seconds, while tuning plus B also totals 60 seconds. More calls save time under these assumptions; fewer do not recover the search overhead.
The arithmetic assumes fixed per-call timings, valid outputs, one tuning cost and no further overhead. Real compilation, shape changes, measurement noise or concurrency can change the comparison. Record search time separately from steady-state execution, and use repeated measurements with a consistent procedure.
Keep the result within its measured scope
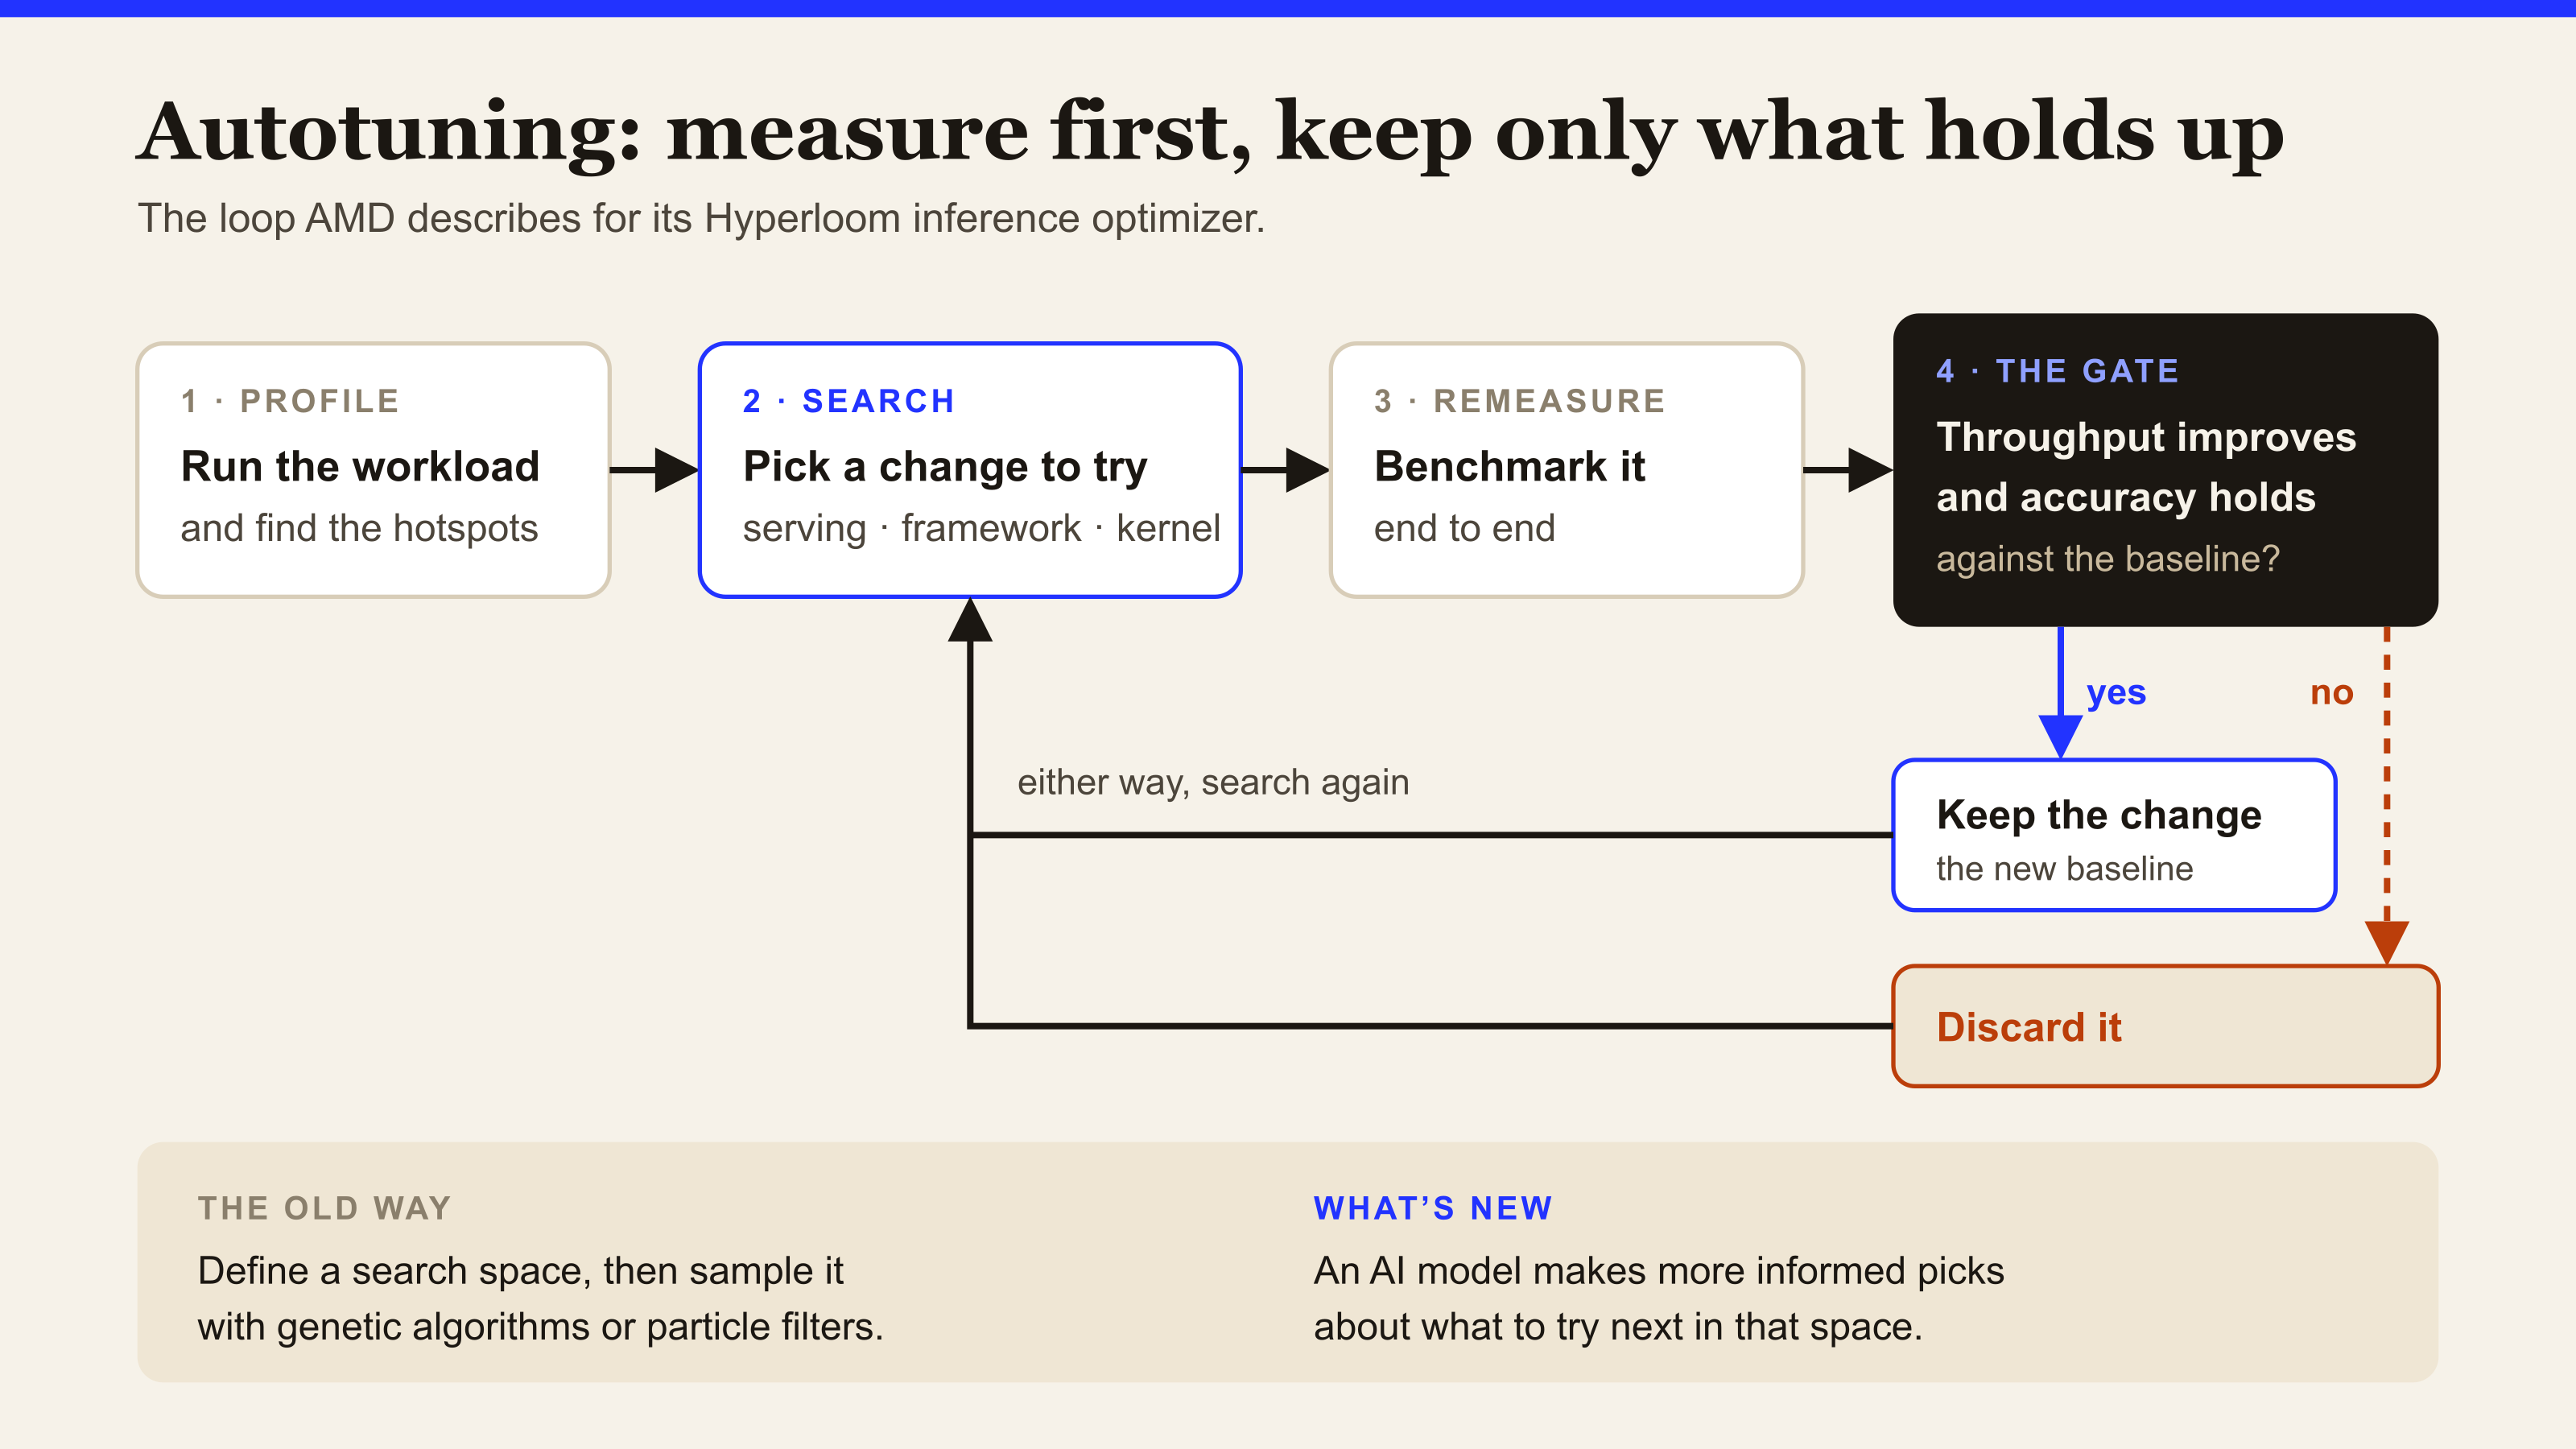
AMD’s Hyperloom description describes remeasuring changes end to end, retaining throughput gains only when accuracy holds, and sweeping different concurrency levels and input/output lengths. A configuration that wins at one operating point need not win at another. Its loop continues only while optimization budget and measured headroom remain and the run has not converged, under a hard cap on cycles.
Separating the older optimization loop from an AI-guided search, Anush Elangovan says, “Search space exploration has been around for a while. Now, what’s new is using AI and LLMs for search space exploration, right?” (episode 72, 24:05).
An AI-selected change still has to pass the same checks. Keep the baseline, tested configuration, workload, correctness result and measurement procedure. The AI hardware hub connects profiling topics, while AI infrastructure covers the serving workload. Pareto frontier explains comparing more than one objective.
Hear it from the guest
“Search space exploration has been around for a while. Now, what's new is using AI and LLMs for search space exploration, right?”
Quotes lightly edited to remove filler words.
Sources
- Triton, autotune — Configs are re-evaluated when key arguments change; evaluation runs the kernel multiple times, with reset_to_zero and restore_value for values updated in place; checked November 2, 2026.
- Hyperloom description — Describes a baseline measurement, keeping a change only when throughput improves and accuracy holds, sweeps across concurrency and input/output lengths, and budget and convergence stopping conditions. Its speedup figures are AMD's own; checked November 2, 2026.