Skip to content

AI, decoded

Should you use open source or proprietary LLMs?

It depends on the job, and most serious teams use both: open when you need control, customization, privacy, or cost efficiency; proprietary when you need top-end quality on certain tasks or the easiest path to start. No one has won the race, so locking into one provider is the mistake. Fireworks AI's Aishwarya Srinivasan told Chain of Thought that DeepSeek V3 was an inflection point for the performance-to-price ratio of open-source models, while vision remained harder for available open models than proprietary ones.

· Updated · Chain of Thought

Level 1: How AI works · 1.4 The model landscape

Open Source AIEnterprise AI

  • 3 episodes
  • 3 guest clips
  • 7 glossary terms
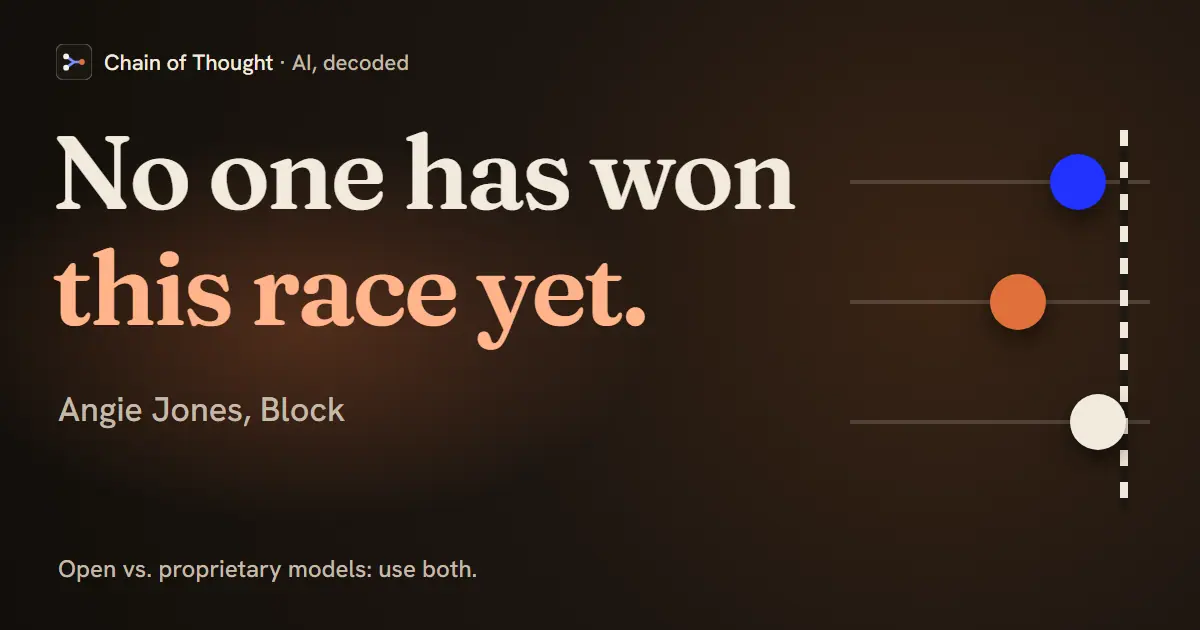
Race lanes where the leader keeps changing, beside Angie Jones's words: No one has won this race yet. Use open and proprietary models together.

In detail

1. Cost and performance

Aishwarya Srinivasan marks the DeepSeek V3 release as the inflection point where open models hit a price-to-performance ratio that made them competitive. For high-volume use cases, open models on your own terms can be the more cost-efficient choice.

2. Control and customization

Open models let you fine-tune and shape the size, the speed, and the behavior. If your use case needs the model tailored to it, open gives you that latitude in a way a closed API does not.

3. Privacy and on-prem

The paid APIs from the major providers do not train on your prompts by default (OpenAI, Anthropic, Google), but retention varies by provider and feature: abuse-monitoring logs are kept for a limited time, and some features that store state keep data until you delete it. If you need zero retention, check what each provider offers and on what terms. If the data cannot leave your hardware at all, open weights you control are the most flexible route, though some proprietary models now ship for air-gapped data centers too.

4. Where proprietary still wins

Aishwarya is clear-eyed about the gaps. Vision capabilities are still stronger in proprietary models, developer experience is smoother, and for some quality-sensitive tasks the closed frontier models are simply better. That is why even open-source advocates keep them in the mix.

The real answer: use both

Angie Jones’s team at Block does not standardize on one model. Claude for software, a GPT model for job functions that lean on reasoning, and local open models for the smaller group of engineers whose machines can run them. The strength is in matching the model to the task, not crowning a winner.

Why it matters

The “open vs. proprietary” debate is framed as a fight. In practice it is a portfolio. The teams getting the most out of AI treat models as interchangeable parts and route each task to the one that fits.

Open and proprietary models as a portfolio, routed per task Your tasks sit in the middle and are routed to the model that fits, as at Block in episode 48: software development goes to Claude, job functions that lean on reasoning may want a GPT model, and a smaller group of engineers whose machines can run them use local open models. On the left, what pulls a task toward open weights: cost efficiency, which Aishwarya Srinivasan dates to DeepSeek V3; control to fine-tune the model's size, speed and behavior; and privacy, zero data retention or running on your own hardware. On the right, what pulls it toward proprietary models: stronger vision capabilities, a smoother developer experience to get started, and top-end quality on some tasks. Angie Jones: no one has won this race yet, so locking in on one provider would be foolish. Not a fight. A portfolio. Each task gets pulled toward the model that fits it. Serious teams route; they don’t crown a winner. PULLS TOWARD OPEN WEIGHTS Cost efficiency The inflection point: DeepSeek V3 Control Fine-tune the size, speed, behavior Privacy Zero data retention, your hardware Aishwarya Srinivasan, Fireworks AI, episode 42 PULLS TOWARD PROPRIETARY Vision Still stronger in closed models Developer experience The easiest path to get started Top-end quality On some quality-sensitive tasks Also Aishwarya Srinivasan, episode 42 BLOCK’S ROUTING · EPISODE 48 Your tasks Software development → Claude Reasoning-heavy roles → may want GPT Niche circles → local open models Many models behind one hosting service (Databricks) at Block “No one has won this race yet.” Angie Jones, Block, episode 48: the best model changes provider week to week, so “it would be foolish of us to kind of lock in on one specific one.” Match the model to the task and keep both kinds in the mix.
A portfolio, not a fight. The routing is Angie Jones’s description of Block in episode 48; the open and proprietary trade-offs are Aishwarya Srinivasan’s, from episode 42. Download the image

Hear it from the guest

“No one has won this race yet. … in any given week, if you say what's the best model out, it'll be from a different provider, right? And so it would be foolish of us to kind of lock in on one specific one.”
Watch on YouTube
“After the DeepSeek v3 model came, we did see that inflection point where the performance and price ratio of what you can really build at a very cost efficient and a very customized manner, something that you have full control on with an open source model compared to a proprietary model, it just went up.”
Aishwarya Srinivasan, Fireworks AI EP 42 · around 30:19 · read the transcript
“So if you have a startup, right, and you rely on API, and then suddenly the API provider changes the model, your entire business is in pieces, right?”

Quotes lightly edited to remove filler words.

From the conversation

This explainer is drawn from these episodes — each carries its full transcript.
Concepts in this explainer

Open WeightsClosed SourceOpen SourceOpen-Source ModelData CenterFrontier ModelLarge Language Model