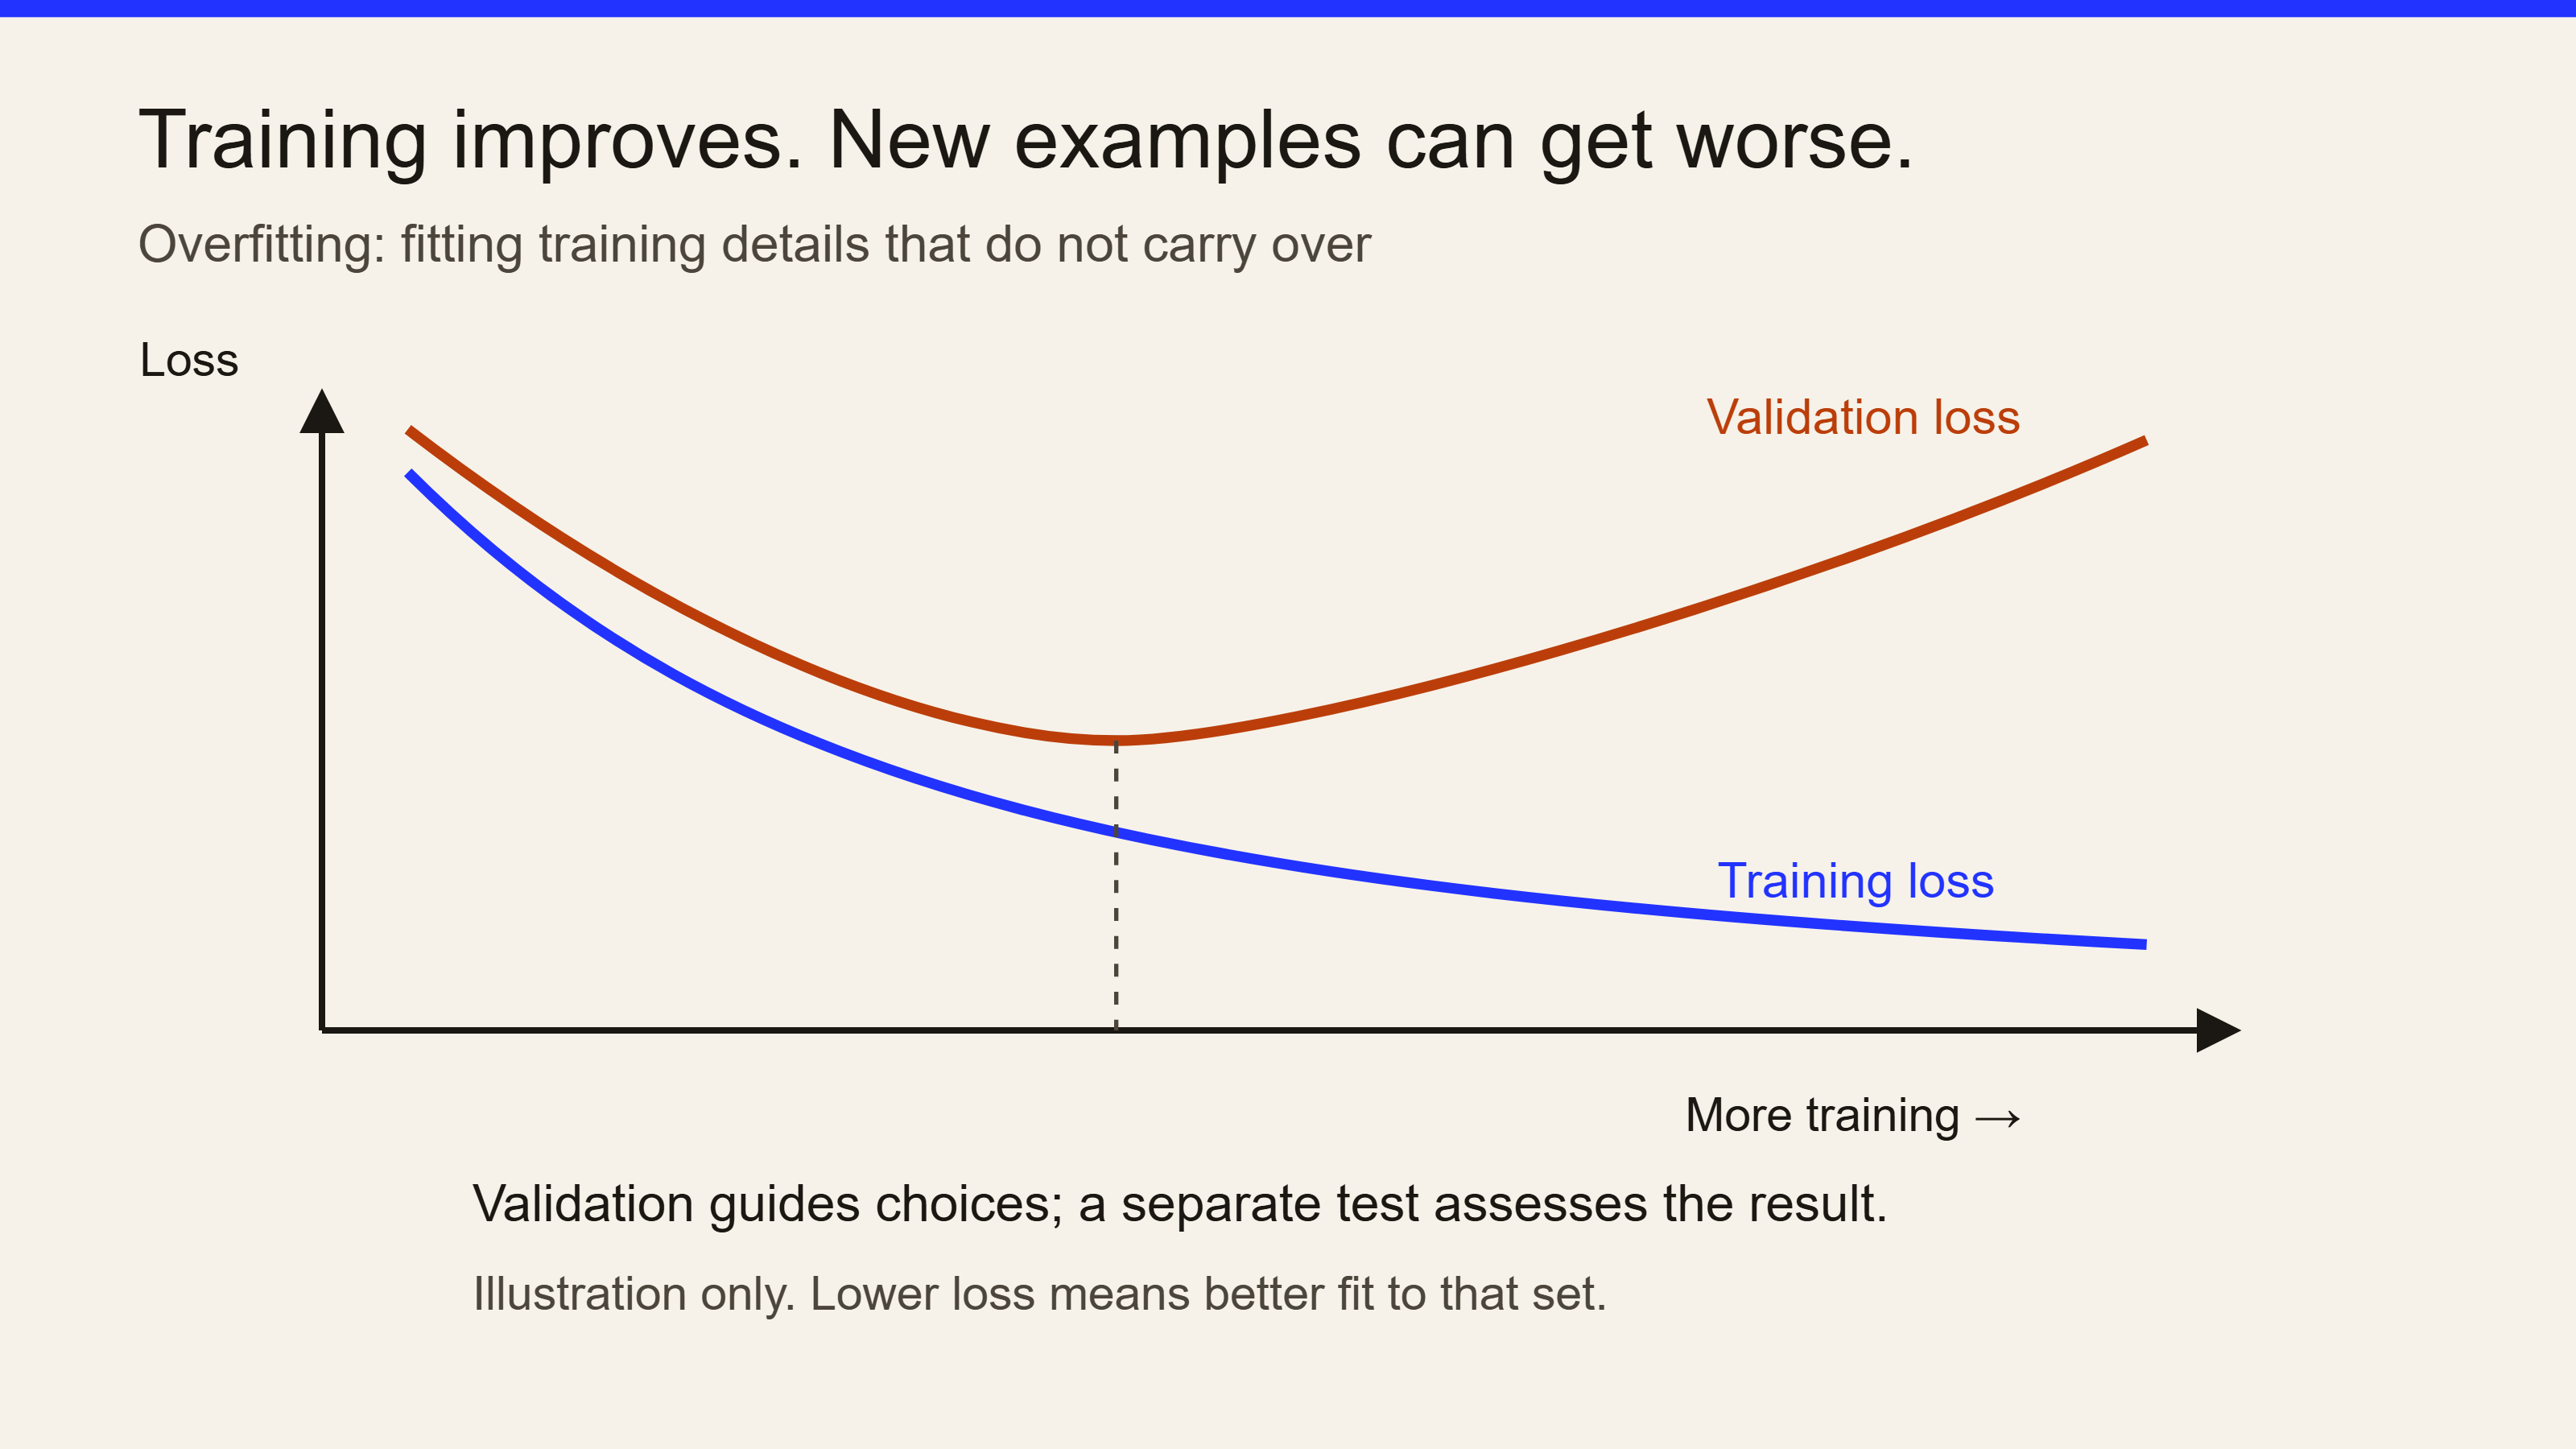
A ticket classifier might learn peculiar wording used by the few agents who labeled its training set. It handles those tickets well but fails on new customers’ wording. This is an illustrative failure, not a measured benchmark: the model has fit details that do not help on the intended task.
Compare training results with validation results on examples that did not fit the model. A falling training loss alongside a rising validation loss is a warning. A gap alone is not proof of its cause: also check for different distributions, label problems or leaked information.
Regularization methods such as dropout, less flexible models, representative training examples, data augmentation and early stopping can help. More training is not always the remedy. Nor does success on one test set prove success under changed conditions. The practical goal is generalization, not a perfect score on examples the model has already seen.
Sources
- Google: Overfitting — Explains training-specific fit and diverging training and validation loss curves.
Go deeper
- scikit-learn: Cross-validation docs
Learn how held-out data and cross-validation estimate performance beyond training examples.