In detail
Failure lives between the agents
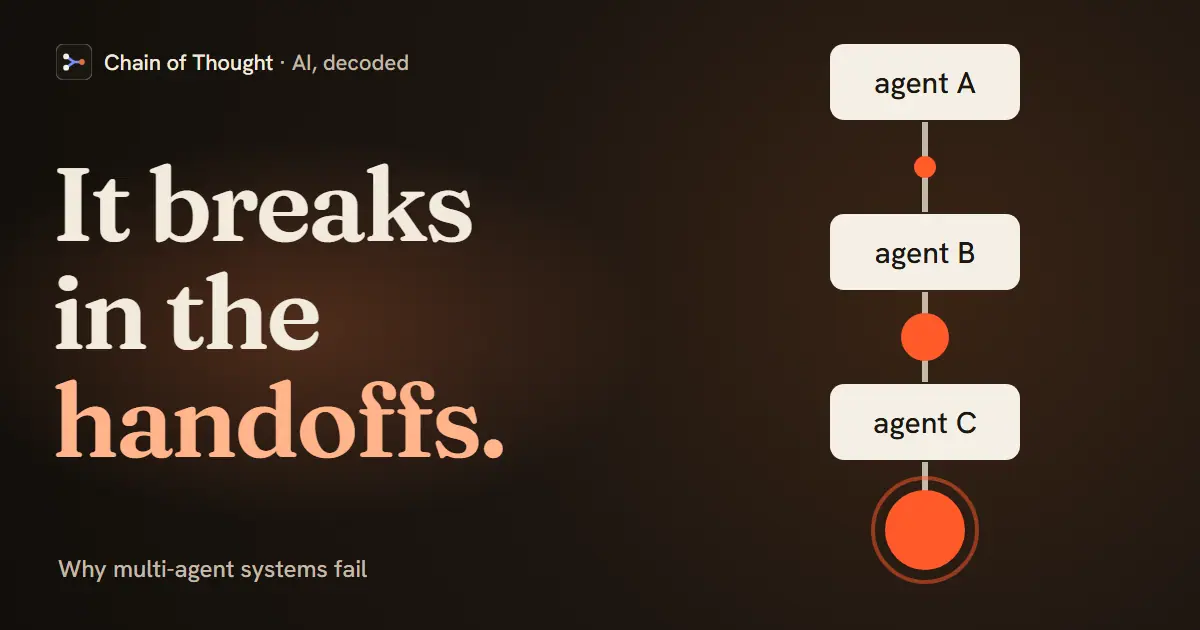
Each agent in a system can work in isolation and the system can still fail, because the weak points are the connections. An agent hands off with missing context. One agent’s hallucination becomes the next agent’s input, which it treats as fact. A small error early in a chain gets amplified at every downstream step. The failure is emergent — it belongs to the system, not to any one component.
Researchers at UC Berkeley put numbers on this in Why Do Multi-Agent LLM Systems Fail?. They start from the observation that multi-agent systems often post only minimal gains over single agents on popular benchmarks, then annotate more than 1,600 execution traces from seven popular frameworks. The resulting taxonomy has 14 failure modes in three groups: problems in how the system is designed, misalignment between agents, and weak verification of the task’s result.
Cascading and systemic risk
Because outputs feed inputs, multi-agent systems turn small faults into large ones. A single mislabeled result, a tool that returns stale data, a compromised agent — any of these can propagate through the whole network. The same property makes them a security surface: an attacker who influences one agent can steer the others. Reliability and security are the same problem viewed from two sides.
Cost compounds too
The gaps cost money as well as accuracy. Anthropic reported that in its own data, agents use about 4 times as many tokens as chat interactions and multi-agent systems about 15 times as many, so they pay off only on tasks valuable enough to cover that. The same post notes that work where every agent needs the same context, or where agents depend heavily on each other, fits multiple agents poorly. A loop between agents that never converges, like the one Lyzr stopped at $300, is the expensive version of that mismatch.
Making them reliable
Treat the system as the unit of analysis. Trace every step so you can see where a failure entered and how it spread; what is AI observability covers what to record. Validate what passes between agents instead of trusting it. Put guardrails on how much autonomy each agent has. And threat-model the cascade paths in advance — ask how a fault in agent A reaches the user — so you catch systemic failures in design rather than in production.
Hear it from the guest
“If you don't have a way of observing what these agents are doing, if you don't have a way of evaluating them, and if you don't have a way of putting guardrails around their behavior, you just don't have an agentic system that's gonna really survive.”
“Make sure that you have criteria for how to evaluate the performance of those agents. And then you look at that team or that coalition or what have you holistically.”
“You won't believe such loop cost us $300 Just the amount of LLM calls it had to take and it had to complete the whole loop. Did it still fix? Answer is no.”
“No one's gonna go trace by trace by trace and try to look for where things are going wrong. It's just not gonna happen.”
Quotes lightly edited to remove filler words.
Go deeper
- Threat Modeling for Multi-Agent AI: Identifying Systemic Risks Follow a failure across agent handoffs, then compare the proposed controls with the episode examples above.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
-
 Mastering Multi-Agent Systems | MongoDB’s Mikiko Chandrasekhar
-
 Architecting Reliable Agentic AI | Cisco’s Giovanna Carofiglio on the AGNTCY Collective
-
 The First Fully Autonomous AI Attack is Coming | Kris Lovejoy, Kyndryl
-
 Why Enterprises Need a Different Approach to AI Agents | Lyzr’s Siva Surendira
-
 The 2025 AI Shift: From Chat to Task Completion & Reliable Action | Galileo Founders
Concepts in this explainer
Multi-agent systemAgent SwarmOrchestrator AgentSubagentLarge Language ModelAccuracyAI HallucinationAI Observability