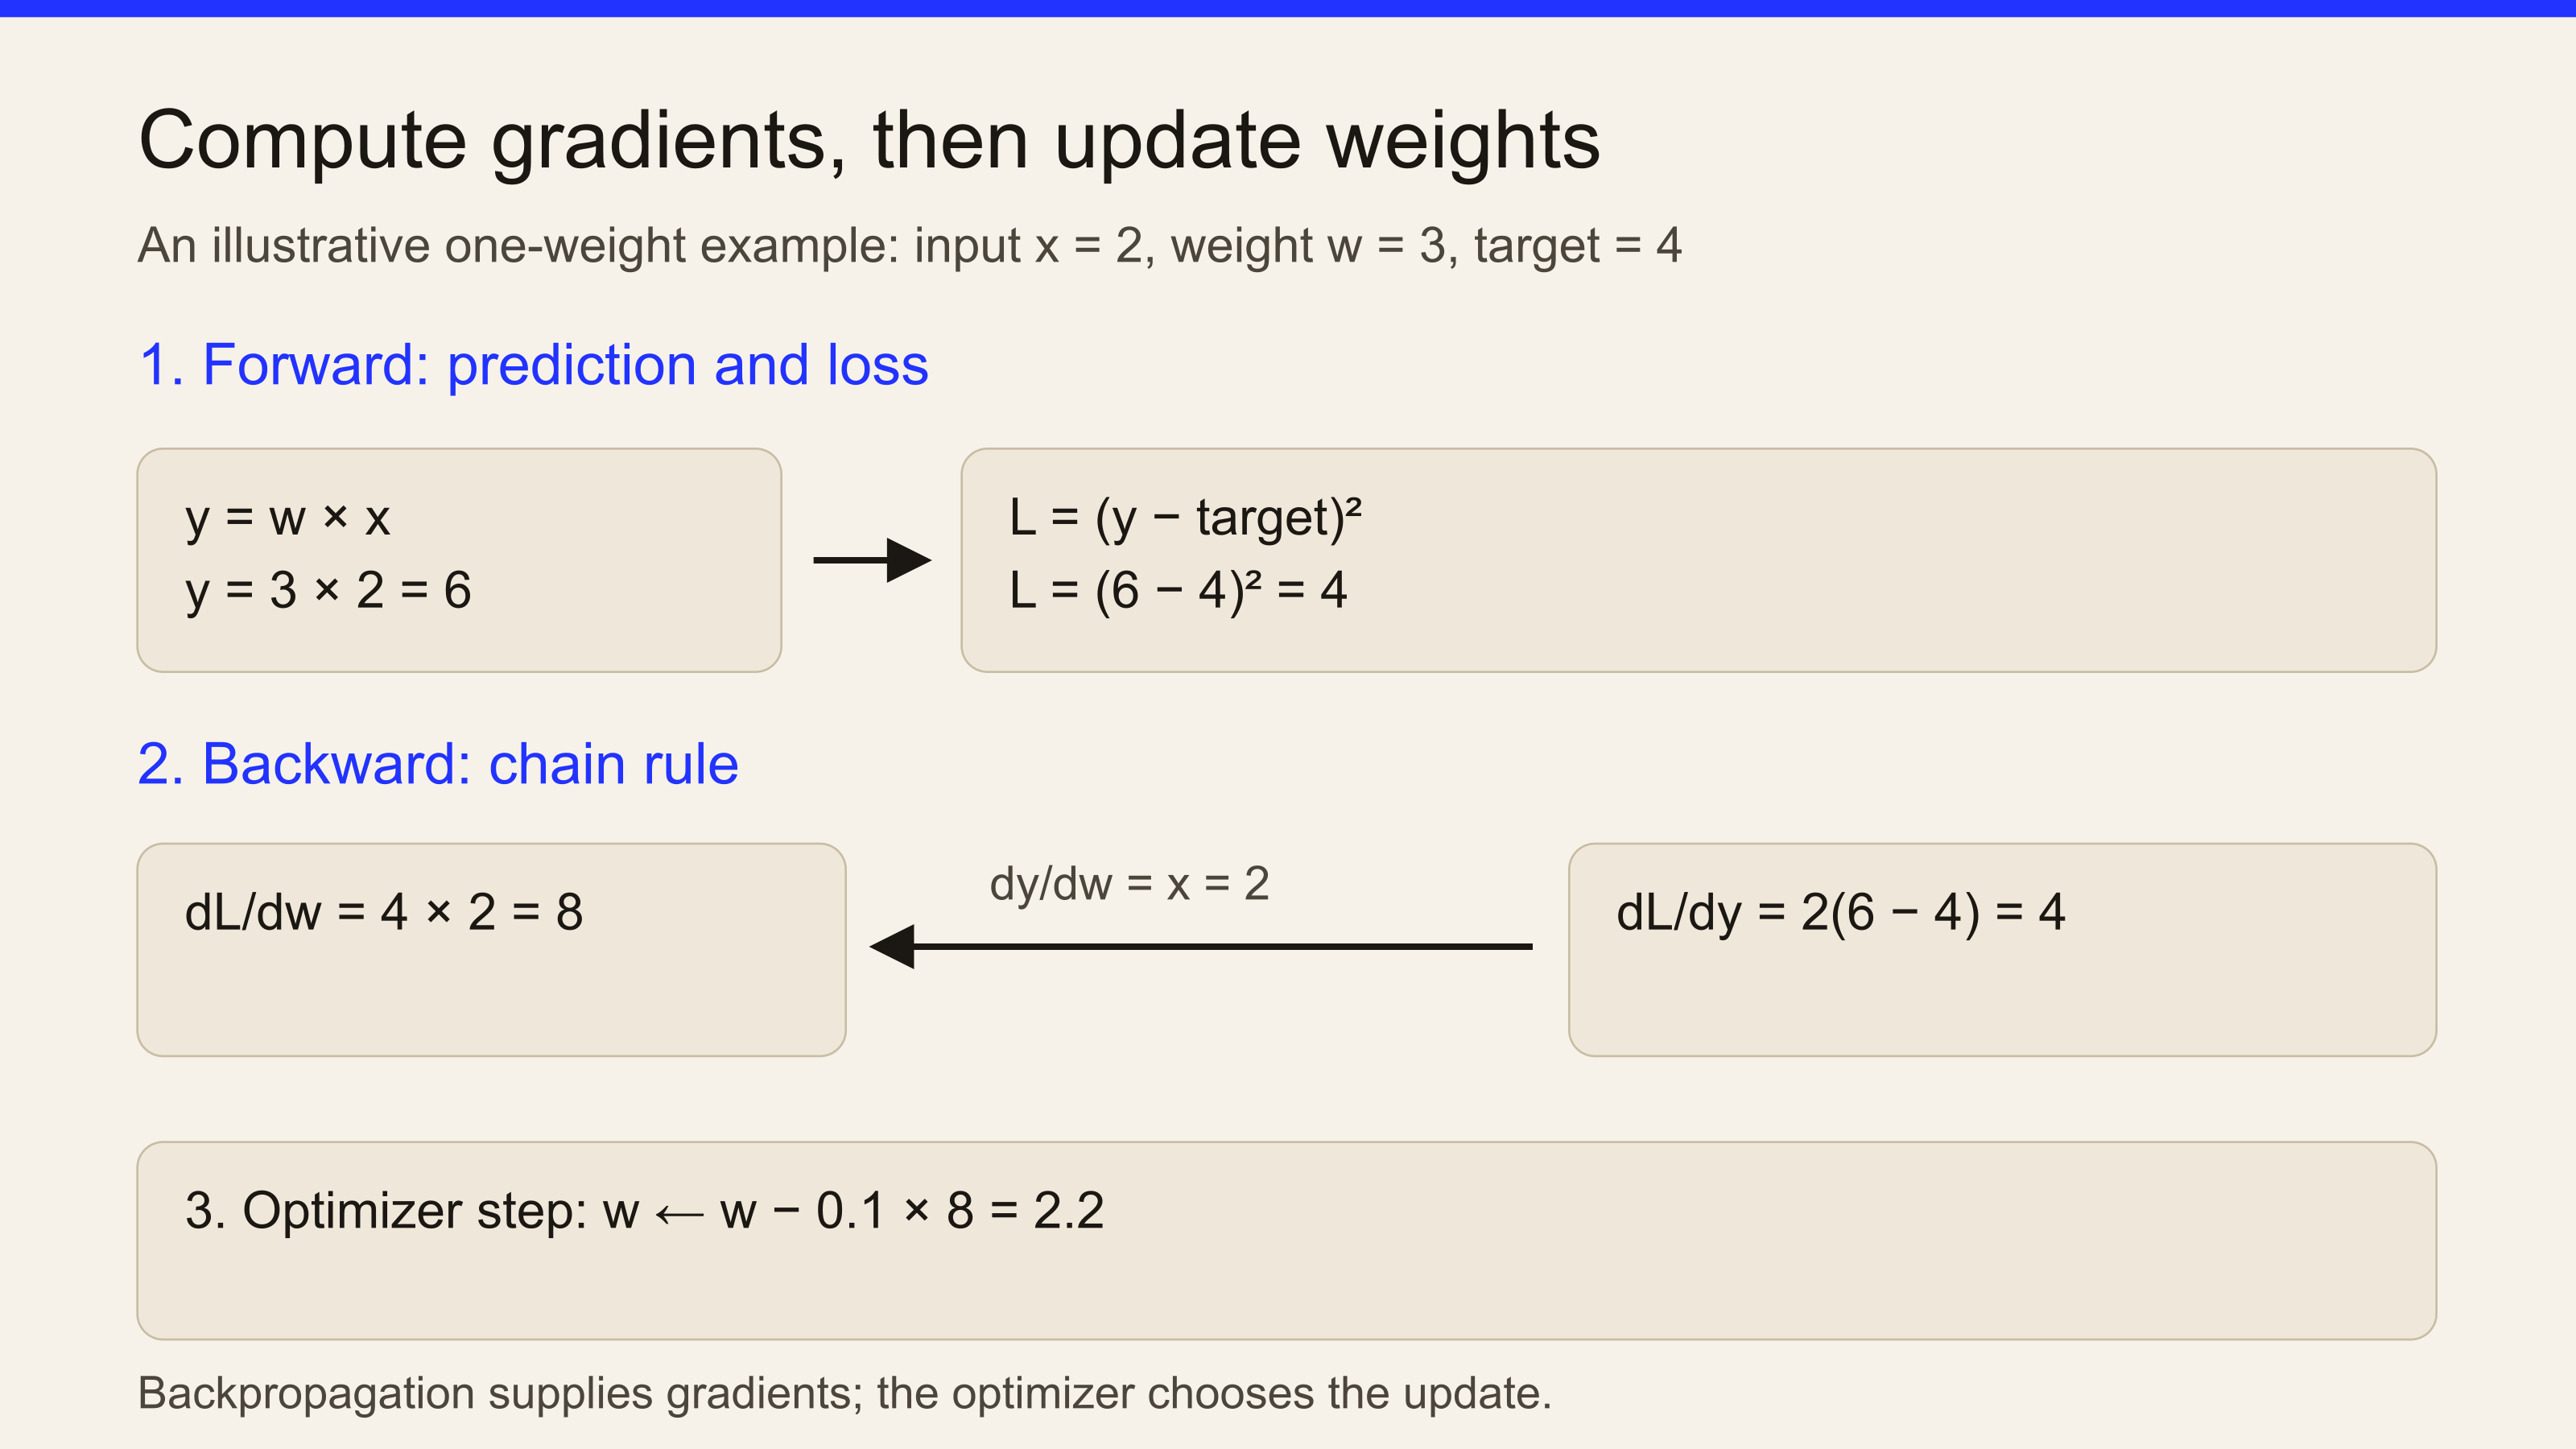
Training first runs a forward calculation, producing a prediction and a loss. Backpropagation works backward through those operations to compute gradients: how sensitive that loss is to each weight and bias. The optimizer chooses how to use those gradients.
For a small example, let the prediction be y = w × x and loss be L = (y − target)². With input 2, weight 3 and target 4, the prediction is 6 and loss is 4. The chain rule gives dL/dw = 2(y − target) × x = 8. A gradient-descent step with learning rate 0.1 changes the weight to 2.2. This example is illustrative, not a general choice of learning rate.
Same gradient, two step sizes
Continue the example. The gradient at the starting weight is 8 whatever happens next; the step size decides what the update does with it. From the same starting weight of 3:
| Learning rate | New weight | New prediction | New loss |
|---|---|---|---|
| 0.1 | 3 − 0.1 × 8 = 2.2 | 4.4 | 0.4² = 0.16 |
| 0.5 | 3 − 0.5 × 8 = −1 | −2 | (−2 − 4)² = 36 |
Both updates use a correctly computed gradient. The larger step overshoots the target and makes the loss nine times worse than where it started. When a training loss rises, check the forward values, the gradients and the update settings as separate questions. PyTorch’s training-loop tutorial splits them into three calls, optimizer.zero_grad(), loss.backward() and optimizer.step(), and notes that gradients add up by default, so a loop that never clears them applies stale gradients on top of new ones (PyTorch, Optimizing model parameters).
The distinction matters when debugging training. Computing the gradient does not guarantee a useful update, a global optimum or good performance on new examples. Ordinary serving inference uses learned parameters without training them; fine-tuning adds a training loop that can use backpropagation.
Sources
- PyTorch: Automatic differentiation with torch.autograd — Shows forward computation, backward gradient propagation, the chain rule and disabling gradient tracking for inference.
- PyTorch tutorial: Optimizing model parameters — Separates optimizer.zero_grad(), loss.backward() and optimizer.step(), and notes that gradients add up by default. Checked November 2, 2026.
Go deeper
- 3Blue1Brown: Backpropagation, intuitively video
See how an error signal changes weights through several layers.