In detail
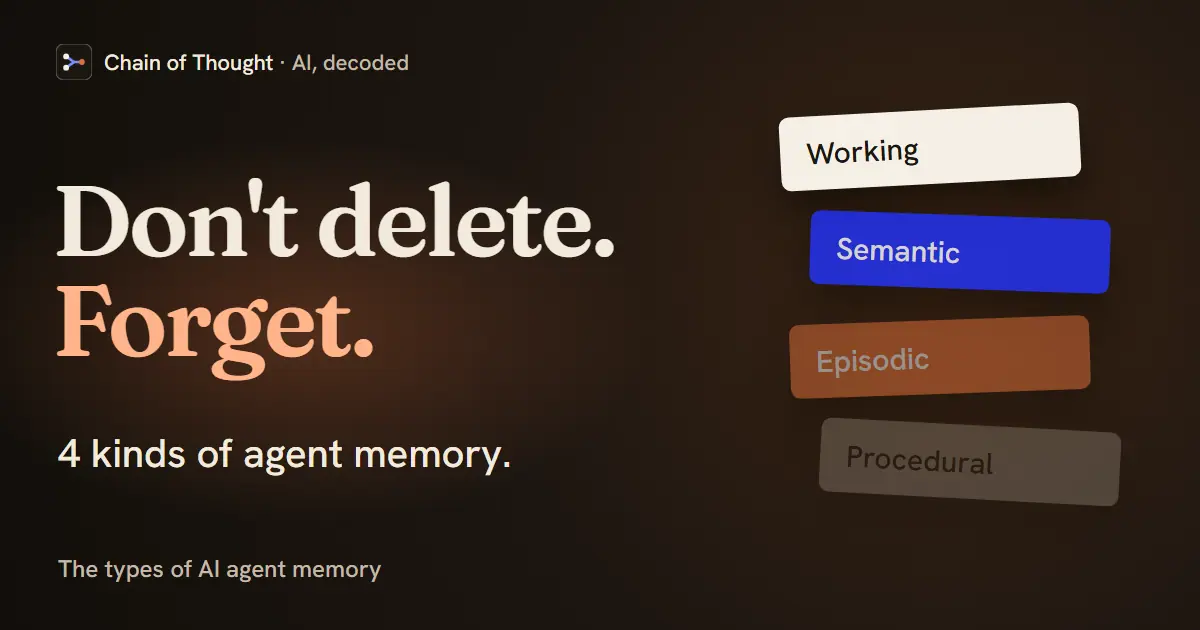
1. Working memory: what it is holding right now
The active context window. The scratch pad. Small, temporary, whatever is on the desk this moment. It is what a basic chatbot relies on, and without the other kinds, your context is gone when the chat ends. Some consumer assistants now add cross-chat memory on top (Claude, for one, carries saved context into new chats), a step toward the semantic and episodic layers below.
2. Semantic memory: the facts it knows
Reference knowledge it can reuse: your policies, your docs, your institutional knowledge. The textbook on the shelf. This is the institutional knowledge an agent pulls from again and again.
3. Episodic memory: what happened
Time-stamped interactions. Past conversations, tied to when they occurred. The diary. This is what lets an agent say “last week you decided X” instead of starting every session from zero.
4. Procedural memory: how to do the task
Skills and routines. The standard operating procedures it runs without re-reasoning every time. Muscle memory. The how-to layer that turns a one-off into a repeatable workflow.
Forgetting and deletion solve different problems
Richmond Alake recommends reducing the retrieval priority of old memories rather than treating every stored item as equally useful. He describes recency, relevance and importance as signals. This is a retrieval design idea, not a rule to retain everything forever. Decide separately what should be superseded, excluded from retrieval, retained for an approved audit purpose, or deleted under the product’s data policy.
Why it matters
Alake’s own agent demo doesn’t lean on a smarter model. It gives the agent separate lanes for each kind of memory. You cannot train a frontier model on your own, but a single developer can build a memory system that remembers better than ChatGPT. Memory is a layer where individual effort can still compete with the big labs.
Memory that outlasts one model
Episodic memory gets more valuable the longer it accumulates, which makes it worth keeping independent of any one model. In episode 77 at 1:36, Kimberly Logan of the Walrus Foundation argues that a longer context window helps only while you stay with one provider; switching models or harnesses should not mean starting over. At 9:59 she cites Walrus’s figure that almost 85% of the memories written are read back more than 30 days later, which she takes as a sign of long-running workflows. That is the company’s own usage data, not an independent benchmark.
Her example at 13:03 is an episodic record used outside coding: a security team snapshots production, compares it with code changes and uses the accumulated history to verify what changed. The test is the same as for the refund policy below: can the next system tell what changed, when, and which record still applies? Walrus Memory sponsored this episode and the season, as Conor discloses at 3:24. For moving memory between models, see how to make agent memory portable and agent memory portability.
Give each remembered fact an owner and a date
The four-part analogy describes what memory is used for. It does not tell you which storage system to buy, which fact wins a conflict, or who may read it. LangChain’s memory overview makes another useful distinction: thread-scoped state supports one conversation; longer-term stores carry information across conversations. A persisted conversation is not necessarily shared institutional knowledge.
Illustrative design: a support agent remembers a refund policy. Store the policy’s source, owner, effective date, tenant and superseded status with the text. Retrieve within the authorized tenant before ranking for relevance. Decide which source has authority before asking the model to summarize conflicting records.
| Test case | What should happen |
|---|---|
| A current 30-day policy conflicts with an older 60-day memory | Use the applicable authoritative policy and identify the conflict |
| A similar customer record belongs to another tenant | Do not retrieve or disclose it |
| A remembered preference is explicitly withdrawn | Stop applying it and follow the product’s deletion policy |
| A new conversation resumes a saved task | Recover the task state without treating old approval as permission for a different action |
These are suggested acceptance cases. They test whether the memory is usable, current and authorized, rather than whether a vector search returned something similar.
For choosing an implementation layer, compare Mem0, Zep, Letta and LangMem and run the changing-fact pilot before adopting a memory tool.
Check yourself
Does a highly relevant memory outrank a newer approved policy? Relevance alone cannot answer that. Check authority and applicability. Conor’s essay on agent amnesia explains why persistence matters; the context explainer connects persistent context to systems of record and changing business definitions.
Hear it from the guest
“There's a principle I like to communicate to people, which is you don't delete information in memory engineering, you forget.”
“For example, a single developer can't train a GPT 4-5 like model, right? But a single developer can build a memory system that can remember better than a chat GPT.”
“So Blackboard memory is where you have agents kind of come together to post like partial solutions, and essentially it's read write,”
“Memory is fundamentally recording of continuous state changes that is happening in the agentic systems and with agents.”
“Any time that you need something to accumulate knowledge over time. and understand how that knowledge has changed and what's applicable and what's not.”
Quotes lightly edited to remove filler words.
Go deeper
- Memory overview Distinguishes thread-scoped state from cross-session memory and explains semantic, episodic and procedural memory.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
Concepts in this explainer
Agent Memory PortabilityAgent MemoryAI AgentContext WindowAI BenchmarkFrontier ModelSystem of Record