In detail
The problem it solves
You cannot have humans read every response an AI system produces in production. There are too many, and they arrive too fast. LLM-as-a-judge fills that gap: a second model reads each output and scores it against a rubric — relevance, factual grounding, completeness, tone, safety — so you can score more outputs or sample systematically. The judge’s score still needs validation.
Why a rubric matters more than the model
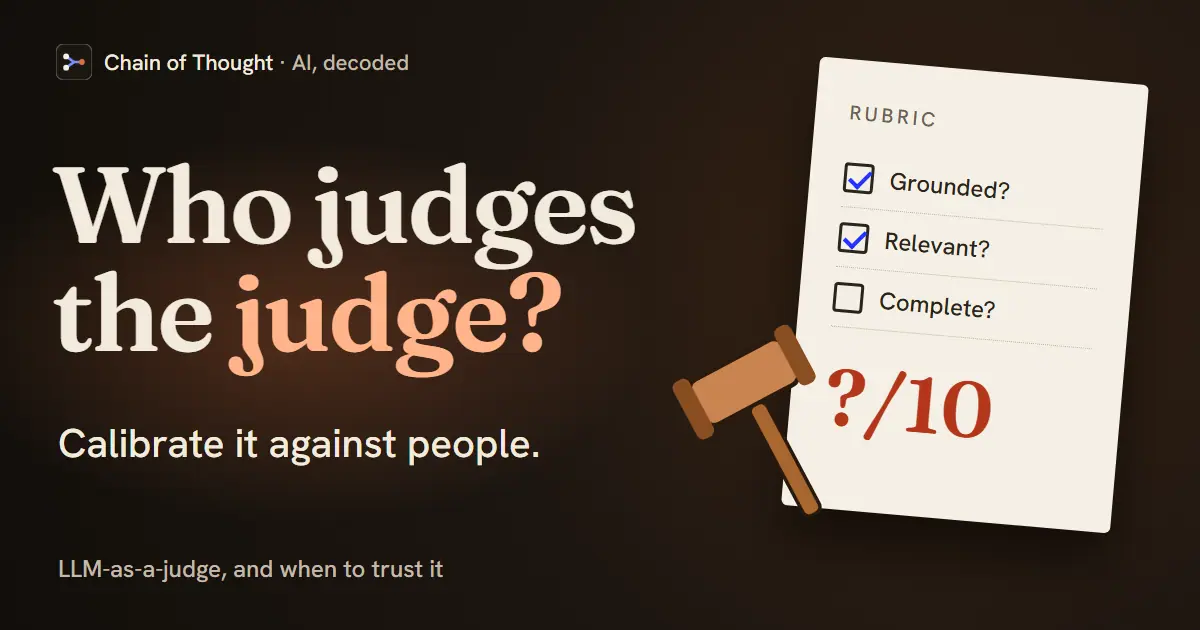
A judge is only as good as what you ask it to check. “Rate this 1-10” produces noise. A judge that checks specific, named criteria — “is every claim supported by the retrieved context,” “does it answer the question that was asked” — produces a signal you can act on. The rubric is where your definition of “good” lives.
Where it breaks, and the guardrail
A judge model carries its own biases. It can favor longer answers, prefer its own phrasing, or wave through a fluent answer that is wrong. The fix is calibration: score a batch by hand, compare to the judge, and adjust until they agree on your data. Then keep humans on the decisions that matter most. The judge handles volume; people handle the cases where being wrong is costly.
Who calibrates matters when the domain is specialized. MongoDB’s Rachelle Palmer used medical applications as the high-risk example in episode 14 at 27:27. An engineering team can’t tell whether a diagnosis is right, so it needs a partnership with a doctor, nurse or physician assistant to prove the application is accurate (27:57). From there, she says, teams can have the LLM “act as a judge against itself with that subject matter expertise,” for example through fine-tuning or repair loops in which models play different roles (28:24). MongoDB’s own repair loop, described at 40:52, keeps fixing generated code against a custom evaluation metric, and a human steps in when it can’t reach the score (41:20). The episode aired in season two, which Galileo sponsored while Conor worked there; Galileo CTO Atindriyo Sanyal co-hosted (0:22).
Try it: a minimal judge and calibration loop
For a retrieval-based assistant, a workable start is two separate checks: is every factual claim supported by the retrieved context, and does the answer address the question asked. Keeping them separate tells you which part failed. Then:
- Write the failures into the rubric first. Collect answers your system could get wrong on your data: one that invents a detail missing from the context, one that is accurate but misses the question, and an honest “I can’t answer from this.” Decide how a reviewer should label each, including whether that abstention passes.
- Ask for a pass/fail decision and a reason per criterion. A binary call is easier to check against people than a 1-10 score, and the reason shows you where the judge misread the rubric.
- Calibrate against people. Have qualified reviewers label a batch without seeing the judge’s verdicts. Measure agreement per criterion, and read every case where the judge passed an answer a human failed.
- Keep the labeled batch. Re-run it whenever the judge model, the prompt, or the rubric changes.
Illustrative sketch, not production code. The first function builds the judge prompt. The second compares the judge with human labels, where judge stands in for a function that sends that prompt to a model and parses the JSON it returns.
def judge_prompt(question, context, answer):
    return f"""Grade the answer using the question and retrieved context.

grounded: Pass only if every factual claim in the answer is
supported by the context. Do not fill gaps from your own knowledge.

answers_question: Pass if the answer addresses the question asked.
When the context is insufficient, an explicit abstention may pass.

Ignore answer length and phrasing unless they change the meaning.
Return only JSON with keys "grounded" and "answers_question".
Each value must contain "pass" (boolean) and "reason" (string).

Question: {question}
Retrieved context: {context}
Answer: {answer}"""


CRITERIA = ("grounded", "answers_question")

def calibrate(rows, judge):
    # rows: labeled cases, with a human pass/fail per criterion
    if not rows:
        raise ValueError("Provide human-labeled rows")
    tally = {name: {"agree": 0, "false_pass": 0} for name in CRITERIA}

    for row in rows:
        verdict = judge(row["question"], row["context"], row["answer"])
        for name in CRITERIA:
            judge_pass = verdict[name]["pass"]
            human_pass = row["human"][name]
            tally[name]["agree"] += judge_pass == human_pass
            tally[name]["false_pass"] += judge_pass and not human_pass

    return {
        name: {
            "agreement": counts["agree"] / len(rows),
            "false_passes": counts["false_pass"],
        }
        for name, counts in tally.items()
    }
Pick the agreement bar that fits the cost of a mistake, and write down why you chose it. Watch false passes, where the judge approves an answer a person rejected: in many applications they cost more than false alarms.
Chip Huyen’s example from the GenAI evals panel shows why the rubric needs more than correctness. She pointed to a LinkedIn case study of a job-fit assistant: asked whether a candidate was a good fit for a role, the bot could reply “No, you’re a terrible fit.” The answer was correct, and it was still a bad response. She also warned that judge scores like coherence and relevancy get reported as if they were exact, when they are “very highly dependent on the models you use, on the prompt you use for the judge.” (28:00)
The last stretch of accuracy depends on context only you have. Galileo CEO Vikram Chatterji calls taking an LLM judge from 75% to 95% accuracy the “last mile measurement problem.” The missing accuracy comes from context the model never saw in training: that “CC” means credit card in your company’s parlance, say, or a bank’s internal policies. Have someone who knows the domain review the ambiguous labels and write those rules into the rubric.
Agreement alone can hide the dangerous mistakes
Illustrative calibration set: people label 80 answers acceptable and 20 unacceptable. A judge that passes every answer achieves 80% agreement while missing every bad answer. On those labels, its bad-answer detection rate is zero. That is why the calibration sketch above tracks false passes, rather than reporting agreement alone.
Inspect false passes and false alarms separately for each criterion and failure category. Keep a held-out labeled set that was not used to revise the rubric. A judge that works for tone may still miss wrong policy exceptions. An abstention rule also needs both missing-context cases and answerable cases; otherwise “I don’t know” can win by avoiding the task.
Probe the judge’s shortcuts
The MT-Bench judge study documents position, verbosity and self-enhancement biases in the studied models. For a pairwise comparison, swap the presentation order and inspect changed verdicts. For a groundedness check, include a fluent unsupported answer and a short accurate one. The research does not establish that every current judge has the same error rate; run these probes on your own judge.
Treat the candidate answer as untrusted content. Include an answer that tells the evaluator to award a pass. Delimit the evidence and answer, but verify resistance through testing; formatting alone does not create a security boundary. Use deterministic checks for permissions and recorded actions before asking a judge about communication quality.
Check yourself
Which is more useful for your release: a judge’s 90% agreement score or the list of cases it falsely approved? You need both, plus the cost of those errors. Choose the gate from the product’s requirements before tuning to it, and recheck when the model, rubric or dataset changes. Continue with testing an AI system to separate exact contracts from language judgments.
Hear it from the guest
“Sometimes we just get lazy because we have to explain what it is and we'll just skip the step and hoping AI judges will figure it out and it doesn't quite go that way.”
“But instead it's the last mile context, which you have as an organization. It's about your use case, your organization, your context, and no LLM on the planet can have all of that.”
“When you have a hard instance, the model and the checker are going to fail in exactly the same cases. So 80% checking 80% is going to be like 82%.”
“What is needed in these areas of very high risk is a tight partnership between engineering that's building the applications and the subject matter experts who can proof the outputs of an LLM.”
Quotes lightly edited to remove filler words.
Go deeper
- Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena Documents position, verbosity and self-enhancement biases in the studied judges; benchmark agreement is not a guarantee for your application.
- Using LLM-as-a-Judge for Evaluation Connects judge design to error analysis and human labels, with a worked evaluation process.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
-
 Practical Lessons for GenAI Evals | Chip Huyen & Vivienne Zhang
-
 Explaining Eval Engineering | Galileo's Vikram Chatterji
-
 Every AI Agent Has an Evaluation Gap | Alex Ratner, Snorkel AI
-
 Why LLMs Are Plausibility Engines, Not Truth Engines | Dan Klein, Scaled Cognition
-
 Using AI to Modernize Your Legacy Applications | MongoDB’s Rachelle Palmer
Concepts in this explainer
Pairwise EvaluationLLM as a JudgeLarge Language ModelAccuracyAI EvaluationGenerative AIFaithfulnessFine-Tuning