In detail
Separate a content judgment from an action permission
An agent can turn a mistaken judgment into a tool call that changes something. Guardrails address different parts of that path. Calling a check a guardrail tells you little about its mechanism or reliability.
NVIDIA’s NeMo Guardrails documentation includes checks that ask an LLM to assess content, and says their performance depends on the model. These checks can be useful while still missing an attack or rejecting a legitimate request. Code that invokes a classifier does not turn its judgment into a certainty.
| Check or control | What it can decide | What still needs testing |
|---|---|---|
| Model-based content check | Whether a request or response appears to violate a policy | Missed violations, false alarms and behavior on new inputs |
| Argument validation | Whether a tool call has the expected structure and values | A valid call can still request an unauthorized action |
| Authorization or approval gate | Whether a particular action is permitted before execution | Policy correctness, credential scope and coverage of every action path |
Put decisive action checks before the effect
A response filter can withhold a final answer. It cannot rewind a tool action that already happened. Even an input check may finish too late if it runs alongside the agent. The OpenAI Agents SDK guide describes parallel input checking and the possibility of tool execution before cancellation, as well as checks before and after function-tool execution. Check the actual framework and tool path you use.
OWASP’s excessive-agency guidance recommends limiting capabilities and permissions, requiring approval for high-impact actions, and enforcing authorization in downstream systems. For an email-drafting assistant, that can mean exposing draft creation without send capability, or making each send wait for approval of the exact recipient and message. The credentials and every route to the send operation must respect that boundary.
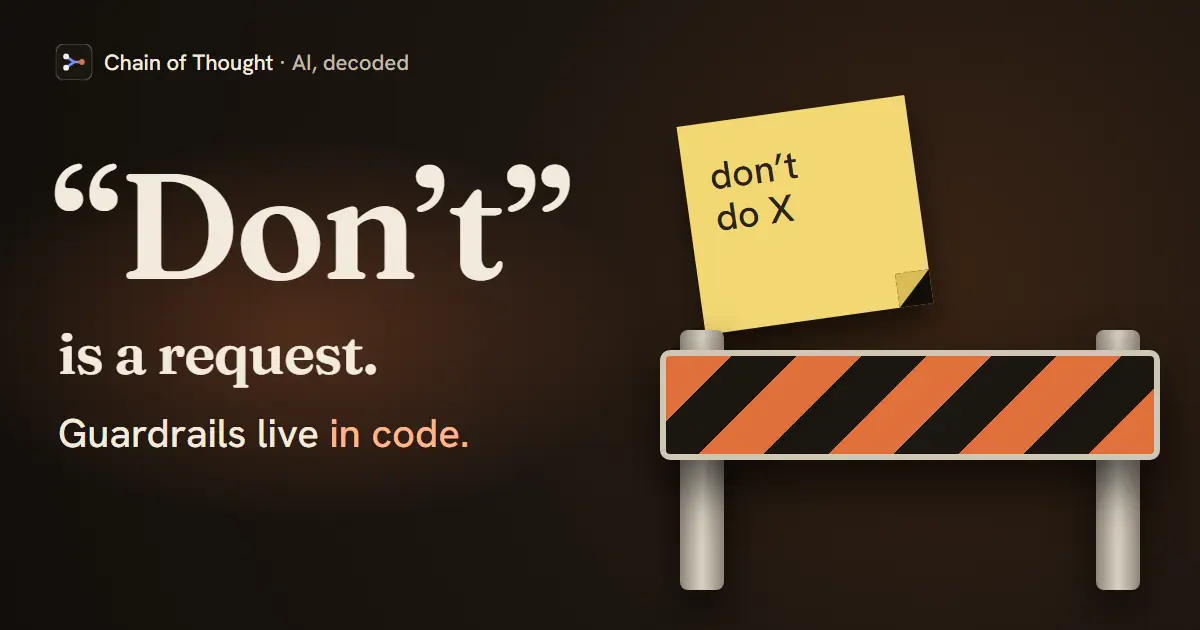
The barrier in the illustration represents this kind of action limit. The broader guardrail toolkit also includes fallible content checks. Keeping enforcement outside the agent’s control is an architectural requirement to verify, not a guarantee conferred by a label.
Check the boundary
These fictional cases illustrate the design questions. They do not run an agent or establish that an implementation is secure. Choose an answer before opening each explanation.
A safety classifier approves an unsafe email, and the tool has send permission. Can the email still be sent?
Yes, in this example there is no other gate. The classifier's wrong approval does not remove the tool's authority. A recipient rule or an approval requirement would need enforcement before the send operation.
Every send checks valid approval for that exact message and recipient. Can a model's claim of approval satisfy the gate?
No, under this case's stated design the gate independently verifies approval. The model's claim is not that evidence. The implementation still needs tests for forged, missing and stale approvals, changed message details and alternate send paths.
An email has been sent when the final-output filter rejects the response. Does that rejection undo the send?
No. Withholding the response does not undo the completed send. Put the permission and approval checks before the action they must prevent; evaluate response checks separately.
Test coverage, timing and failure behavior
Our suggested checklist is to name the action and resource each check covers, then test a permitted case and a nearby prohibited one. Check tool calls, retries, handoffs and alternate paths. Decide what a timeout, unavailable checker or ambiguous verdict should do before releasing the workflow. For a required pre-action approval, execution must wait for a valid result.
Evaluate model-based checks on legitimate requests as well as attacks. OWASP’s prompt-injection guidance recommends layered mitigations and adversarial tests; it does not present a foolproof filter. The episode moments below provide the interview context for why these limits matter. Read agent identity and permissions for the surrounding authority model and sandboxing for execution containment.
Hear it from the guest
“I feel like then in the next phase, a lot of companies kind of, like, took the LLM sometimes back and not let them have these interactions because they could just be talked into doing the wrong stuff too easily.”
“I think if we have the right guardrails in place, the LLMs will take a more front and center customer facing seat again, and if they can be trusted.”
“We're wanting to build highly predictable applications on top of a foundation, which is, by definition, unpredictable.”
“When we think about guardrails, it's typically like these prompts or these instructions that we can set in the system prompt for the model, but the model may choose to disregard those guardrails at some point”
“What I see people trying to do is apply deterministic rules to inherently autonomous systems.”
Quotes lightly edited to remove filler words.
From the conversation
This explainer is drawn from these episodes — each carries its full transcript.
-
 Architecting Reliable Agentic AI | Cisco’s Giovanna Carofiglio on the AGNTCY Collective
-
 The AI Agent Trust Gap: Bridging Risk to Reliability | Elastic’s Philipp Krenn
-
 The Critical Infrastructure Behind the AI Boom | Cisco CPO Jeetu Patel
-
 AI in 2025: Agents & The Rise of Evaluation-Driven Development | Galileo's Yash Sheth & Atindriyo Sanyal
-
 The First Fully Autonomous AI Attack is Coming | Kris Lovejoy, Kyndryl
Concepts in this explainer
AI GuardrailsToxicitySandboxingAI AgentGenerative AILarge Language ModelNon-Human Identity